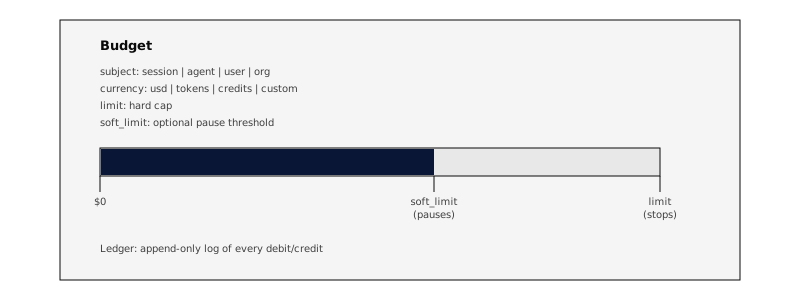
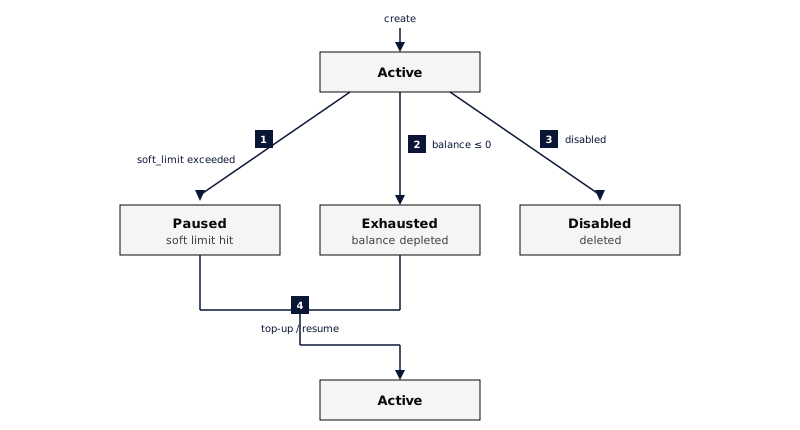
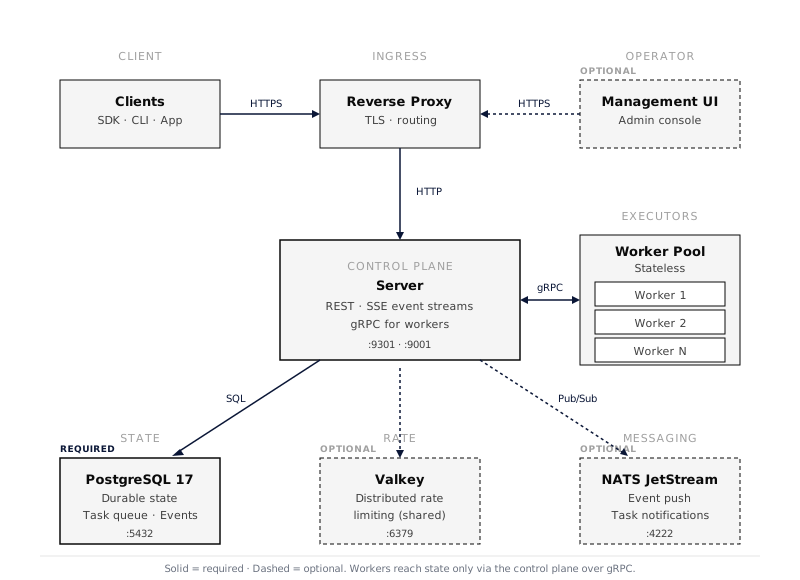
Getting Started: platform concepts, deployment, and the feature surface of a running Everruns --- # Everruns Documentation > Tutorials, how-to guides, reference, and explanation for building and operating Everruns agents. Source: Everruns is a **durable agentic harness engine** built on Rust. It provides APIs for managing agents, sessions, and long-running tasks, with real-time SSE event streaming and PostgreSQL-backed durability. Build directly inside a Rust application with the [Everruns Framework](https://docs.everruns.com/framework/), or use the Platform and SDK documentation for a durable deployment and remote clients. To skip operating the Platform entirely, use the hosted edition at [Everruns Cloud](https://app.everruns.com). ## What kind of help do you need? The documentation is organised by what you’re trying to do. [Everruns Cloud](https://app.everruns.com) — Use the hosted Platform without running it yourself. Open in early access, free for now, bring your own model provider keys. [Framework](https://docs.everruns.com/framework/) — Build and run agents in a Rust process with the application-facing everruns crate. [Learn — Tutorials](https://docs.everruns.com/tutorials/run-an-agent/) — Step-by-step lessons that end with a running agent. Start here if you're new. [Do — How-to guides](https://docs.everruns.com/how-to/) — Task-oriented recipes for common problems. Use these when you know what you want to build. [Understand — Explanation](https://docs.everruns.com/explanation/) — Background and design rationale. Read these when reference docs aren't enough on their own. [Look up — Reference](https://docs.everruns.com/api/) — API endpoints, event types, capability catalog, CLI flags, environment variables. The dry stuff. ## Getting started fast 1. Choose [Everruns Cloud](https://app.everruns.com) for the hosted Platform, the [Framework](https://docs.everruns.com/framework/) for an in-process Rust application, or [Docker Compose](https://docs.everruns.com/getting-started/docker-compose/) to run the full Platform yourself. 2. Run the [Framework quickstart](https://docs.everruns.com/framework/quickstart/) or follow the [SDK tutorial](https://docs.everruns.com/tutorials/building-agents-using-sdk/). 3. Browse [How-to guides](https://docs.everruns.com/how-to/) to do something specific. ## Popular destinations [Core concepts](https://docs.everruns.com/explanation/concepts/) — Harness, agent, session, capability, event — what they are and how they compose. [Capabilities catalog](https://docs.everruns.com/capabilities/) — Every built-in capability with tools, parameters, and dependencies. [Event reference](https://docs.everruns.com/event-reference/) — Every event type in the Everruns event protocol, with payloads. [REST API reference](https://docs.everruns.com/api/) — OpenAPI-generated reference for every endpoint. [Everruns Framework](https://docs.everruns.com/framework/) — Application-facing Rust agents, models, tools, sessions, events, and extension points. [SDKs](https://docs.everruns.com/features/sdk/) — Official client libraries for Rust, Python, and TypeScript. [CLI](https://docs.everruns.com/features/cli/) — Command-line interface for managing agents, sessions, and conversations. [Architecture](https://docs.everruns.com/explanation/architecture/) — Control plane, workers, durable execution — and why. [Environment variables](https://docs.everruns.com/sre/environment-variables/) — Every configuration knob for the control plane and workers. ## More features [Agent triggers](https://docs.everruns.com/features/agent-triggers/) — Wake an agent on a recurring schedule and inspect its runs. [Session participants](https://docs.everruns.com/features/session-participants/) — Invite agents into a shared session and address one for a turn. [Agent and user memory](https://docs.everruns.com/features/memory-scopes/) — Learn the persistence, mount paths, and privacy rules for scoped memory. --- # Author an agent blueprint > Contribute a code-defined specialist agent from a capability, with a typed configuration contract the spawn path enforces Source: An **agent blueprint** is a code-defined specialist agent: a baked-in prompt, a set of private tools, a model-selection strategy, an iteration bound, and a narrow configuration surface. A host agent delegates to it through the ordinary [sub-agents](https://docs.everruns.com/capabilities/sub-agents/) tool without gaining access to its internals. Reach for a blueprint when work needs different tools, instructions, or model economics than the parent agent — repository scouting, catalog benchmarking, any job where the parent should get the answer without carrying the tools that produced it. Blueprints are not persisted user-created agents; they ship with a capability and are available wherever that capability is enabled. ## Contribute the blueprint A capability contributes blueprints by implementing `agent_blueprints()`. The returned `AgentBlueprint` carries everything the child runtime needs: ```rust fn agent_blueprints(&self) -> Vec { vec![AgentBlueprint { id: "repo_scout", name: "Repo Scout", description: "Search repositories for code, files, and issues. \ Read-only agent for codebase exploration.", model: BlueprintModel::Fixed("claude-haiku-4-5-20251001".to_string()), system_prompt: REPO_SCOUT_PROMPT, tools: vec![Box::new(SearchCodeTool), Box::new(ReadFileTool)], max_turns: Some(15), config_schema: Some(json_schema_for::()), }] } ``` The `description` is what a parent agent reads when deciding whether to delegate, so write it as a routing decision: what the blueprint is for, and when to pick it. `model` chooses one of three strategies. `Fixed` pins a model the host cannot override, which suits specialist work with a known cost/quality target. `Default` names a model the validated config may override. `Inherit` takes the parent’s model, for work that genuinely needs the parent’s characteristics. Tools listed here are **private**. They are instantiated only for the blueprint’s own child session and never appear in the host agent’s tool list. ## Define configuration as a type Derive the config schema from a Rust struct rather than writing JSON by hand. The struct is the single source of truth: field set, bounds, defaults, and descriptions all reach the spawning agent from one place. ```rust use everruns_capability::json_schema_for; use everruns_capability::schemars::JsonSchema; use serde::{Deserialize, Serialize}; /// The same ceiling the search tools apply to their own arguments. const MAX_REPOS: u32 = 50; /// Configuration for the repository scout. #[derive(Debug, Clone, Serialize, Deserialize, JsonSchema)] #[serde(deny_unknown_fields, default)] #[schemars(crate = "everruns_capability::schemars")] pub struct RepoScoutConfig { /// Maximum number of repositories to scan. #[schemars(range(min = 1, max = MAX_REPOS))] pub max_repos: u32, } impl Default for RepoScoutConfig { fn default() -> Self { Self { max_repos: 10 } } } ``` Three habits keep the contract honest: * **Express each bound once.** Write it as a constant shared by the schema attribute and the code that enforces it at runtime, so a schema edit cannot drift from the clamp it describes. * **Write doc comments for the caller.** They become the schema descriptions the spawning agent reads. Implementation notes belong in ordinary `//` comments. * **Close the object** with `deny_unknown_fields` unless the blueprint genuinely accepts open configuration. Requiring configuration is a matter of leaving a field without a default: fields serde cannot default become `required` in the derived schema, and the spawn path rejects a call that omits them. ## What the spawn path enforces Configuration is validated against the derived schema **before** a child session exists, so a declared bound constrains the host rather than merely advising the model. A spawn is rejected when: * a value violates the schema — out of range, wrong type, missing a required property; * the config carries a key the schema does not define (with `deny_unknown_fields`); * the blueprint declares no schema at all but config was supplied. The error returned to the calling agent names the violations and includes the schema, so a model can usually correct its own call and retry. Validation governs what a **host** may configure. It is not a substitute for a tool checking its own arguments: keep the runtime clamps in the blueprint’s tools, so a misbehaving child agent stays inside the same envelope. Configuration can only select behavior the blueprint intentionally exposes. It cannot replace the system prompt, inject tools, bypass model policy, or expand capability permissions. ## Delegation and lifetime A spawned blueprint session is a real durable session. It takes part in the same message, event, task, workspace, cancellation, and recovery infrastructure as any other sub-agent; the difference is only how its runtime is assembled. The session persists the blueprint identity and its validated config, so a worker can reconstruct the same runtime after a retry or handoff. The blueprint itself stays a stateless template. Follow-ups address the durable session, not the blueprint. ## Worked examples Two blueprints ship in-tree and are worth reading as references: * [`integrations/github/src/lib.rs`](https://github.com/everruns/everruns/blob/main/integrations/github/src/lib.rs) — the minimal case: one config field, a pattern constant shared with the runtime check that enforces it. * [`integrations/openrouter/src/model_scout.rs`](https://github.com/everruns/everruns/blob/main/integrations/openrouter/src/model_scout.rs) — the fuller case: numeric bounds tied to runtime constants, a nested config type, and a spend budget. ## Related * [Sub-agents](https://docs.everruns.com/capabilities/sub-agents/) — the delegation tool blueprints are invoked through * [GitHub Scout](https://docs.everruns.com/capabilities/github-scout/) — a shipped blueprint from the caller’s side --- # Budgets > Cap session spending in dollars, tokens, or custom credits, with soft pause thresholds and automatic enforcement. Source: Budgets let you cap how much a session (or agent, user, or organization) can spend. When a session hits its budget, Everruns stops scheduling further LLM calls. This prevents runaway costs from long-running or misbehaving agents. ![Budget Structure](https://docs.everruns.com/_astro/budget-structure.Co0JWPRZ_Z1X89MI.svg) ## How It Works After every LLM generation, Everruns computes the cost and debits it from any active budgets for that session. In subagent trees, session-scoped budgets are shared at the root session, so child and grandchild turns spend from the same pool. If the balance reaches zero, the session stops. 1. **LLM call completes**: Everruns extracts token counts (input + output). 2. **Compute debit**: Converts tokens to the budget’s currency: * `usd`, uses per-model pricing (cost per million tokens for input/output) * `tokens`, raw token count * `credits`, 1 credit = 1,000 tokens * Custom currencies fall back to token count 3. **Debit ledger**: Appends an immutable ledger entry and updates the balance. 4. **Evaluate rules**: Checks thresholds: * Balance at 20% of limit → warning event * Spending exceeds soft limit → session pauses * Balance reaches zero → session stops Enforcement is **post-hoc**: the check runs after each LLM call, not before. This avoids blocking the hot path. The last generation may slightly overshoot the limit, this is expected and by design. ## Currencies | Currency | Unit | How cost is calculated | | --------- | ----------------------- | ----------------------------------------------------------------------------- | | `usd` | US dollars | Per-model pricing from model profiles (input/output rates per million tokens) | | `tokens` | Raw tokens | Direct count of input + output tokens | | `credits` | 1 credit = 1,000 tokens | Token count divided by 1,000 | | Custom | Any string | Falls back to raw token count | USD budgets use real per-model pricing. A $10 budget on GPT-4o will last much longer than $10 on Claude Opus, because the per-token cost differs. ## Soft Limits and Pausing A **soft limit** pauses the session before hitting the hard stop. This is useful in interactive sessions where a human can decide to top up or stop. 1. Spending exceeds `soft_limit` → budget status becomes `paused` 2. The worker detects the pause between atoms → stops scheduling the next LLM call 3. Session transitions to `paused` state 4. User can resume by increasing the limit, topping up, or calling the resume endpoint For headless sessions (no human watching), the hard limit fires at balance zero and terminates the turn. ## Stacked Budgets Multiple budgets can apply to the same session. The **most restrictive** budget wins. This lets you combine different types of limits: * A **$10 USD session budget** caps dollar cost * A **2M token budget** caps total token usage regardless of model pricing Budget stacking is enforced across the session hierarchy: root session, app channel, app, agent, user, and organization. The most restrictive matching budget wins. ## CLI Usage Set a budget when creating a session: ```bash # $10 USD budget (currency defaults to usd) everruns sessions create --budget-limit 10 # Explicit currency everruns sessions create --budget-limit usd:10 # With soft limit — pauses at $8, hard stop at $10 everruns sessions create --budget-limit usd:10 --budget-soft-limit usd:8 # Token budget everruns sessions create --budget-limit tokens:2000000 # Stacked — both limits, whichever hits first everruns sessions create --budget-limit usd:10 --budget-limit tokens:2000000 ``` ## MCP Usage The `agent_run` MCP tool accepts budget parameters directly: ```json { "name": "agent_run", "arguments": { "message": "Analyze this codebase", "agent_id": "agent_abc123", "budget_limit": 10.00, "budget_currency": "usd", "budget_soft_limit": 8.00 } } ``` Budget operations are also available as catalog commands via the `execute` tool: ```bash # Create a budget for an existing session create_budget --subject_type session --subject_id ses_xxx \ --currency usd --limit 10 --soft_limit 8 # Check a session's budget status check_session_budgets --session_id ses_xxx # Top up an exhausted budget top_up_budget --budget_id bdg_xxx --amount 5 --description "Extra allowance" # List all budgets for a session list_session_budgets --session_id ses_xxx ``` ## API ### Budget CRUD ```plaintext POST /v1/budgets Create budget GET /v1/budgets List budgets (?subject_type=&subject_id=) GET /v1/budgets/{id} Get budget with current balance PATCH /v1/budgets/{id} Update limit / soft_limit / status DELETE /v1/budgets/{id} Soft-delete (sets status=disabled) ``` ### Budget operations ```plaintext POST /v1/budgets/{id}/top-up Add credits (negative ledger entry) GET /v1/budgets/{id}/ledger Paginated ledger entries (?limit=&offset=) GET /v1/budgets/{id}/check Check budget status ``` ### Session shortcuts ```plaintext GET /v1/sessions/{id}/budgets List budgets for this session GET /v1/sessions/{id}/budget-check Check all budgets (session + hierarchy) POST /v1/sessions/{id}/resume Resume paused budgets ``` ### Create a session budget ```bash curl -X POST https://your-instance/api/v1/budgets \ -H "Authorization: Bearer $API_KEY" \ -H "Content-Type: application/json" \ -d '{ "subject_type": "session", "subject_id": "ses_01abc...", "currency": "usd", "limit": 10.00, "soft_limit": 8.00 }' ``` ### Top up an exhausted budget ```bash curl -X POST https://your-instance/api/v1/budgets/{budget_id}/top-up \ -H "Authorization: Bearer $API_KEY" \ -H "Content-Type: application/json" \ -d '{ "amount": 5.00, "description": "Emergency top-up" }' ``` If the budget was `paused` or `exhausted` and now has positive balance, it automatically reactivates. ## Events Subscribe to budget events via SSE to react in real time: | Event | When | Key data | | ------------------ | ------------------------------- | ------------------------------------------- | | `budget.warning` | Balance at 20% of limit | `budget_id`, `balance`, `limit`, `currency` | | `budget.paused` | Spending exceeds soft limit | `budget_id`, `balance`, `soft_limit` | | `budget.exhausted` | Balance reaches zero | `budget_id`, `balance`, `limit` | | `budget.resumed` | User resumes after pause/top-up | `budget_id`, `balance`, `limit` | ## Agent Awareness The `budgeting` capability is included in the **Generic harness** by default. Any session using the Generic harness automatically gets budget-aware behavior: * The agent’s system prompt includes a “Budget Awareness” section with guidelines for efficient output when budget is constrained * The agent gets a `check_budget` tool to query remaining balance before expensive operations When budget is running low, a budget-aware agent will prioritize completing current tasks efficiently rather than exploring new directions. ## Budget Lifecycle ![Budget Lifecycle](https://docs.everruns.com/_astro/budget-lifecycle.CcFpzAwp_Z16kT5Q.svg) --- # Context Compaction > How Everruns manages LLM context windows through automatic compaction strategies, observation masking, summarization, and hierarchical memory tiers Source: Long-running agent sessions accumulate messages until they exceed the model’s context window. When that happens, the LLM rejects the request. **Context compaction** automatically reduces the conversation size so the agent can keep working without losing important information. Everruns provides multiple compaction strategies that can be combined. The default `auto` strategy cascades through all of them in order, from cheapest (free) to most expensive (LLM call), stopping as soon as the context fits. ![Context Window](https://docs.everruns.com/_astro/context-window.MRvRSZA5_Ws5VN.svg) ## How It Works Compaction operates at two points: 1. **Proactively**: before each LLM call, Everruns estimates the token count. If it exceeds a configurable budget threshold (default 85% of the model’s context window), compaction runs *before* the call is made. This avoids the latency of a failed request. 2. **Reactively**: if the LLM still returns a `RequestTooLarge` error (estimation can undercount), the compaction cascade runs and the request is retried automatically. In both cases, the same cascade of strategies executes: ![Compaction Cascade](https://docs.everruns.com/_astro/compaction-cascade.CHRb7Otd_Z2dF1WF.svg) The UI shows a divider between messages whenever compaction happens: > **Context compacted** · 142 → 38 messages · observation\_masking+summarization Click the divider to see the cascade details, which strategies ran, how many messages each step produced, and the time taken. ## Strategies ### Auto (default) Runs all strategies in order. Stops as soon as context fits. This is the recommended setting for most use cases. ### Observation Masking Replaces old tool outputs with compact summaries while keeping the message structure intact. This is free (no LLM call) and preserves tool call IDs for tracing. Two summary formats: | Format | Example | When to use | | -------------------- | ----------------------------------------------------------- | --------------------------------- | | `one_line` (default) | `[read_file → 47 lines, 2340 bytes]` | Most cases, minimal footprint | | `head_tail` | First 3 lines + `... (14 lines omitted) ...` + last 3 lines | When partial output context helps | The most recent N tool outputs are always kept verbatim (default: 5). ### Native Provider Compaction Delegates compaction to the LLM provider’s own endpoint. Currently supported by OpenAI’s Responses API (`/responses/compact`). When available, this can be more intelligent than generic strategies since the provider understands its own tokenization. Everruns sends either a stateful response handle or a standalone transcript to the compact endpoint, never both. The returned ordered context is encrypted at rest as a durable checkpoint and reused across later turns and process restarts. Each request combines the latest checkpoint for the exact provider/model with raw messages written after its source boundary; changing provider or model falls back to raw history. Compaction never deletes or rewrites session events. Public `context.compacted` events contain only counts, timing, strategy, and an optional checkpoint identifier. Provider-native encrypted context remains confined to the internal provider and storage paths. ### Summarization Uses an LLM to generate a structured summary of older messages. The summary replaces those messages in context and is wrapped in `[CONVERSATION_SUMMARY]` tags so subsequent compactions can re-summarize it. You can configure: * Which model to use (default: same as the agent) * What information to preserve (decisions, files modified, errors, etc.) * Custom instructions appended to the summarization prompt ### Aggressive Trim Last resort. Drops the oldest messages to fit within the token budget. The system prompt and the most recent messages are always preserved. This is lossy, dropped messages cannot be recovered unless Infinity Context is enabled. ## Generic Harness Defaults The built-in **Generic** harness enables both `compaction` and `infinity_context` by default. Together they keep long sessions unbounded without manual configuration. | Capability | Role | Default in Generic | | ---------------------- | ------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------- | | **Infinity Context** | Limits how many messages are loaded from the database into the prompt; provides `query_history` for retrieval | `context_budget_tokens: 100000`, `min_recent_messages: 10` | | **Context Compaction** | Reduces the size of messages that *are* in the prompt, masking tool outputs, summarizing, or trimming | `strategy: auto`, `proactive: true`, `budget_percent: 0.85` | The flow for a long-running Generic session: ![Compaction Session Flow](https://docs.everruns.com/_astro/compaction-session-flow.CE_nRiHo_1TFtua.svg) No configuration is needed, creating a session with the Generic harness gives you this behavior out of the box. To customize, override either capability’s config on the agent or session level. ## Configuration Compaction is a capability configured per agent or harness via `AgentCapabilityConfig`. ### Default (auto strategy, proactive) ```json { "capabilities": ["compaction"] } ``` ### Custom strategy and budget ```json { "capabilities": [ { "ref": "compaction", "config": { "strategy": "auto", "proactive": true, "budget_percent": 0.85 } } ] } ``` ### Observation masking only (no LLM calls) ```json { "capabilities": [ { "ref": "compaction", "config": { "strategy": "observation_masking", "observation_masking": { "keep_recent_tool_outputs": 10, "summary_format": "head_tail" } } } ] } ``` ### Summarization with a cheaper model ```json { "capabilities": [ { "ref": "compaction", "config": { "strategy": "summarization", "summarization": { "model": "claude-haiku-4-5-20251001", "preserve": ["decisions", "files_modified", "errors", "api_keys"], "instructions": "Focus on architecture decisions and API contract changes" } } } ] } ``` ### Full configuration with memory tiers ```json { "capabilities": [ { "ref": "compaction", "config": { "strategy": "auto", "proactive": true, "budget_percent": 0.80, "observation_masking": { "keep_recent_tool_outputs": 5, "summary_format": "one_line" }, "summarization": { "model": null, "preserve": ["decisions", "files_modified", "errors", "current_plan"], "instructions": null }, "memory_tiers": { "hot_messages": 20, "warm_messages": 100 } } } ] } ``` ## Configuration Reference ### Top-level | Field | Type | Default | Description | | ---------------- | ------- | -------- | -------------------------------------------------------------------------------- | | `strategy` | string | `"auto"` | Compaction strategy: `auto`, `native`, `observation_masking`, or `summarization` | | `proactive` | boolean | `true` | Compact before hitting context limits (recommended) | | `budget_percent` | float | `0.85` | Trigger proactive compaction at this fraction of the context window | For `auto` and `native`, proactive pressure invokes provider-native compaction when the driver supports it and stores the result as a durable checkpoint. The driver’s effective model context window takes precedence over the built-in profile, so external drivers can report their actual limit. Stateful `previous_response_id` requests skip local proactive pressure checks because their request body is only a delta over provider-held context; reactive too-large recovery remains available. A native result must materially reduce provider-reported tokens, or serialized bytes when token usage is unavailable: at least 5%, with a 32-unit floor for small measurements. Smaller results do not install or replace a checkpoint and do not emit `context.compacted`. A newly installed checkpoint is not proactively replaced again until a meaningful raw-message suffix has accumulated. Failed and no-op native attempts are also held behind a retry watermark until estimated input grows by both 4,096 tokens and 5%, avoiding repeated compact calls against the same source. Branch and rollback selection ignore watermarks from a different transcript lineage. When it is re-armed, the next native compact request preserves the prior opaque checkpoint items in order before appending that suffix, for both proactive and reactive compaction. ### Observation Masking | Field | Type | Default | Description | | -------------------------- | ------- | ------------ | ---------------------------------------------------------- | | `keep_recent_tool_outputs` | integer | `5` | Number of recent tool outputs to keep verbatim | | `summary_format` | string | `"one_line"` | How to summarize masked outputs: `one_line` or `head_tail` | ### Summarization | Field | Type | Default | Description | | -------------- | -------------- | ----------------------------------------------------------- | --------------------------------------------------------- | | `model` | string \| null | `null` | Model for summarization. Null = same as the agent’s model | | `preserve` | string\[] | `["decisions", "files_modified", "errors", "current_plan"]` | Information categories to preserve in summaries | | `instructions` | string \| null | `null` | Custom instructions appended to the summarization prompt | ### Memory Tiers | Field | Type | Default | Description | | --------------- | ------- | ------- | --------------------------------------------------------------- | | `hot_messages` | integer | `20` | Recent messages kept verbatim (full content) | | `warm_messages` | integer | `100` | Older messages with observation masking applied to tool outputs | Messages beyond hot + warm are in the **cold tier**: replaced with a conversation summary. If [Infinity Context](https://docs.everruns.com/capabilities/infinity-context/) is enabled, cold-tier messages remain queryable via `query_history`. ## Memory Tier Diagram ![Memory Tiers](https://docs.everruns.com/_astro/memory-tiers.DavDwkfC_Z16HEh7.svg) ## Combining with Infinity Context Compaction and [Infinity Context](https://docs.everruns.com/capabilities/infinity-context/) are complementary: * **Infinity Context** limits how many messages are loaded from the database into the prompt, and provides `query_history` for retrieval. * **Compaction** reduces the size of messages that *are* in the prompt, making tool outputs smaller, summarizing old turns, or trimming when nothing else works. For long-running sessions, enable both: ```json { "capabilities": [ "infinity_context", { "ref": "compaction", "config": { "strategy": "auto", "proactive": true } } ] } ``` With both active, the flow is: 1. Infinity Context limits messages loaded (e.g., last 100 messages) 2. Compaction masks old tool outputs in those messages 3. If still over budget, summarization or trim kicks in 4. Cold-tier messages remain accessible via `query_history` ## Events Compaction emits two SSE events: | Event | When | Key fields | | -------------------- | ------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------- | | `context.compacting` | Semantic compaction starts | `reason` (proactive\_budget, request\_too\_large, manual), `strategy`, `messages_before`, optional `tokens_before` / `bytes_before` | | `context.compacted` | Material semantic reduction completes | `strategy_used`, `messages_before`, `messages_after`, optional before/after token or byte metrics, `duration_ms`, `steps[]`, optional `checkpoint_id` | Each step in the cascade is recorded with its strategy name, resulting message count, and duration. Provider-encrypted native compact content is never included in these public events. Observation masking alone remains an outbound model-view optimization and does not emit `context.compacted` because it installs no semantic checkpoint. ## Best Practices * **Start with defaults.** The `auto` strategy with `proactive: true` handles most cases well. * **Lower `budget_percent`** (e.g., 0.70) if your agents use large tool outputs frequently, this gives more headroom before the context fills. * **Increase `keep_recent_tool_outputs`** if your agent often references recent tool results across multiple turns. * **Use a cheaper model for summarization** (e.g., Haiku) to reduce cost and latency when the summarization step runs. * **Enable Infinity Context** alongside compaction for sessions that run for hours or days. * **Customize `preserve`** to match your agent’s domain, if your agent tracks database schemas or API contracts, add those to the preserve list. ## See Also * [Infinity Context](https://docs.everruns.com/capabilities/infinity-context/), Message history windowing and retrieval * [Capabilities Overview](https://docs.everruns.com/capabilities/), How capabilities are configured * [Harnesses](https://docs.everruns.com/features/harnesses/), Where capability configs are applied * [Events](https://docs.everruns.com/features/events/), SSE event streaming reference --- # Embedding Everruns > Choose between the application-facing Framework and low-level host composition. Source: For an application that runs agents in its own Rust process, start with the [Everruns Framework](https://docs.everruns.com/framework/) and the `everruns` crate. Its offline [quickstart](https://docs.everruns.com/framework/quickstart/) needs no server, worker, database, network, or credentials. Low-level embedding is for applications that are themselves execution hosts: servers, evaluation harnesses, research runtimes, or specialized systems that must replace backend stores, platform definitions, or orchestration phases. Those hosts compose `everruns` with `everruns-host` and the focused crates they need. The useful low-level boundary, security obligations, and crate-selection guidance now live in [Custom backends](https://docs.everruns.com/framework/custom-backends/). --- # ID Schema > How Everruns formats and validates public resource identifiers, Stripe-style prefixed IDs. Source: Every resource in the Everruns API, agents, sessions, skills, knowledge bases, and so on, is identified by a **prefixed public ID**. The prefix tells you at a glance what kind of resource you are looking at; the suffix is an opaque 32-character token. This pattern was popularized by Stripe (`cus_`, `sub_`, `pi_`). Treat the suffix as a meaningless string, do not parse it, sort by it, or infer information from it. The only guarantees the API makes about an ID are its format, its uniqueness within an organization, and its stability over the lifetime of the resource. ## Format All resource identifiers use the same shape: ```plaintext {prefix}_{32-hex-chars} ``` * `{prefix}` is a short lowercase token that identifies the resource type (for example `agent`, `session`, `skill`). * `_` separates the prefix from the suffix. * `{32-hex-chars}` is an opaque 32-character lowercase hexadecimal token. Example: ```plaintext agent_5c7f3a91b24e48d6a0e91f3b7c4d2e85 ``` Identifiers match a fixed pattern: the resource’s prefix, an underscore, then exactly 32 lowercase hexadecimal characters. For an `agent`, the literal regex is `^agent_[0-9a-f]{32}$`. The API rejects malformed values with `400 Bad Request`. ## Treat the suffix as opaque The suffix carries no public meaning. In particular: * **Do not sort by it.** Use `created_at` (or whatever timestamp field the resource exposes) for chronological ordering. * **Do not infer age, ordering, or shard placement from it.** The encoding may change without notice. * **Do not parse it as a UUID.** The hex format is a transport convenience; future resources may use different internal schemes while keeping the same wire format. This decoupling is intentional. The internal database key for a resource and its public ID are deliberately separate concepts, clients only ever see the public ID. ## Client-Supplied IDs For resources that accept client-supplied IDs on create, you can pass your own `id` as long as it matches the format above and uses the correct prefix for the resource type. If you omit `id`, the server assigns one. A subset of resources additionally expose `PUT /v1/{resource}/{id}` as an upsert: the same call creates the resource if it does not exist (`201 Created`) and updates it in place if it does (`200 OK`). Where supported, this makes idempotent provisioning straightforward, replay the same `PUT` and the end state is identical. The OpenAPI reference is the source of truth for which resources support this; not every resource has a `PUT` route. ## Serialization IDs are always serialized as JSON strings. The field name is `id` for the resource itself and `{resource}_id` when referenced from another resource: ```json { "id": "agent_5c7f3a91b24e48d6a0e91f3b7c4d2e85", "session_id": "session_2b8a4d12c673491fae058b7d9c1f6a40" } ``` ## Prefix Reference The prefix is part of the public contract for each resource. The most common ones are listed below; the canonical list lives in the OpenAPI specification. The prefix in the table below is the token that appears before the `_` separator, an `agent` resource has IDs that start with `agent_`. | Resource | Prefix | | -------------- | ---------- | | Agent | `agent` | | Agent version | `agentver` | | Session | `session` | | Skill | `skill` | | Knowledge base | `kb` | | Memory | `mem` | | MCP server | `mcp` | | Schedule | `sched` | | Image | `img` | | User | `user` | | Organization | `org` | ## Design Notes | Question | Answer | | ------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Why prefixed IDs? | They make IDs self-describing and prevent accidentally passing, say, an agent ID where a session ID is expected. | | Why opaque suffixes? | Decoupling the wire format from internal storage gives the platform room to evolve without breaking clients, and prevents callers from leaning on accidental properties (ordering, creation time) that aren’t part of the contract. | | Why lowercase hex? | Case-insensitive matching, URL-safe, easy to copy and paste. | | Are IDs unique across organizations? | Each ID is unique within its owning organization. The same `id` value could in principle appear in two different orgs, but you only ever see IDs scoped to orgs you belong to. | --- # Memory model > How Workspace and Memory relate, the two-tier model for what an agent can read and write. Source: Everruns separates **where the agent works** from **what the agent remembers across runs**. That split is the whole memory model: * **Workspace**: the active working area for a session. Per-run, singleton, ephemeral by default. Mounted at `/workspace`. * **Memory**: org-scoped, named stores. Durable, governed, mountable into Workspaces. RO by default. These two tiers are intentional. Workspace is where an agent does its current task; Memory is where the org persists state it wants reused across tasks. For the shipped organization, agent, and user ownership tiers, including the private `/memory/user` and automatic `/memory/agent` mounts, see [Agent and user memory](https://docs.everruns.com/features/memory-scopes/). ## The two-axis grid Scope × surface, with the same surfaces appearing on both sides: ```text SESSION ORG (Workspace — per run) (Memory — durable, shared) ┌────────────────────────┬────────────────────────┐ Files │ workdir, scratch │ shared docs, code │ ├────────────────────────┼────────────────────────┤ Tables │ session SQL db │ shared datasets (TBD) │ ├────────────────────────┼────────────────────────┤ KV │ run state, notes │ facts, prefs (TBD) │ ├────────────────────────┼────────────────────────┤ Secrets │ per-run creds │ org credentials (TBD) │ └────────────────────────┴────────────────────────┘ ``` Today only the **Files** surface exists on both sides; Tables exist on the Workspace side (session SQL DB). Tabular, KV, secrets, and structured surfaces on Memory are durable design intent, see `knowledge/runtime-resources/memory.md`. ## Org → Session: Mount A Memory does not enter a Workspace automatically. The `memory` capability declares which Memories are mounted, where, and with what access mode. ```text ORG MEMORIES (named, many) ┌──────────────┬──────────────┬──────────────┐ │ mem:crm │ mem:legal-kb │ mem:pricing │ ... └──────┬───────┴──────┬───────┴──────┬───────┘ │ │ │ per-mount RO | RW ▼ ▼ ▼ ┌─────────────────────────────────────────┐ │ SESSION WORKSPACE │ │ │ │ /workspace ← native files │ │ /workspace/mnt/... ← Memory mounts │ └─────────────────────────────────────────┘ ``` A Memory can be mounted into any number of sessions concurrently. The mount is snapshotted at session creation, so later archival or rename of the Memory does not destabilize a running session. ## Session-eye view What the running agent actually sees: ```text SESSION WORKSPACE (one run) ┌────────────────────────────────────────────────────────┐ │ │ │ NATIVE (lives and dies with the session) │ │ ┌──────────┬──────────┐ │ │ │ files │ tables │ │ │ │ /workspace session SQL db │ │ └──────────┴──────────┘ │ │ │ │ MOUNTED (projected from org Memories) │ │ ┌────────────────────────────────────────────────┐ │ │ │ /workspace/mnt/docs ← mem:design [ro] │ │ │ │ /workspace/mnt/orders ← mem:crm [rw] │ │ │ │ /workspace/mnt/legal ← mem:legal-kb [ro] │ │ │ └────────────────────────────────────────────────┘ │ └────────────────────────────────────────────────────────┘ ``` The same tools (`read_file`, `list_directory`, `grep_files`, `bashkit_shell`) traverse native and mounted paths uniformly. Writes to read-only mounts return clear errors; writes to read-write mounts write through to the underlying Memory and are audited. ## Why two tiers, not one A single “everything is Memory” abstraction was considered and rejected for two reasons: 1. **Lifecycle and governance differ.** Workspace files are intermediate, agents probe, edit, discard. Memory is durable shared state with audit, lifecycle (active/archived/deleted), and trust boundaries. Forcing one set of policies on both was wrong for both. 2. **Naming clarity.** “Memory” anthropomorphizes what the agent recalls across tasks. “Workspace” describes the desk it’s working on. Mixing the two names (“session memory” vs “org memory”) forced every sentence to carry a qualifier. External validation: Anthropic’s Claude Managed Agents settled on essentially the same split, workspace files (per-run) plus Memory Stores (`/mnt/memory/`, durable, named, RO/RW mountable). The terminology in this doc mirrors that convention deliberately. ## Invariants * **Scope.** Sessions cannot see other sessions. Memories are the only sharing point. * **Default access.** Memory mounts default to read-only. Read-write is explicit and audited. * **Snapshot mounts.** Mount config is captured at session creation. Archiving a Memory after that surfaces an error rather than disappearing files. * **Source-backed Memories are read-only.** Memories synced from GitHub/Git cannot be mounted read-write; their contents are replaced atomically on sync. * **Indexes are not surfaces.** Vector search or embeddings are an index *over* a surface, not a new surface. Surfaces are addressable storage. ## What is *not* Memory These exist in Everruns but live outside this model: * **Transcripts and events**: the conversation history is the session’s append-only log, not a memory surface. * **Sandboxes**: managed compute environments (`knowledge/runtime-resources/session-sandbox.md`) are a separate primitive from storage. * **Knowledge Bases** (`knowledge/runtime-resources/knowledge-bases.md`), curated entries with stable citation IDs, agent reads via `search_knowledge`. Likely folds into a future “structured” surface of Memory; today it stays separate. ## Mapping to other systems | Concept | Everruns | Claude Managed Agents | Letta / MemGPT | | ---------------------------- | ------------------------- | --------------------- | --------------- | | Per-run scratch | Workspace | Memory Tool | Working memory | | Durable named store | Memory | Memory Store | Archival memory | | Mount access control | RO / RW per mount | RO / RW per attach | n/a | | Background consolidation | , | Dreaming | Reflection | | Multi-surface (files/tables) | Files today; more planned | Files only | Text blocks | ## Further reading * [Agent and user memory](https://docs.everruns.com/features/memory-scopes/), scoped memory mounts, access, and privacy defaults * [`knowledge/runtime-resources/memory.md`](https://github.com/everruns/everruns/blob/main/knowledge/runtime-resources/memory.md), durable design intent for the Memory tier * [`knowledge/runtime-resources/workspace.md`](https://github.com/everruns/everruns/blob/main/knowledge/runtime-resources/workspace.md), Workspace specification (file surface, mount point, git VCS) * [`knowledge/runtime-resources/knowledge-bases.md`](https://github.com/everruns/everruns/blob/main/knowledge/runtime-resources/knowledge-bases.md), curated org knowledge, the curation-first sibling of Memory --- # Network Access Control > Control which hosts and URLs agents can reach using layered allowlists and blocklists on harnesses, agents, and sessions Source: By default, agents with the `web_fetch` capability can access any public URL. **Network access lists** let you restrict which hosts and URLs an agent can reach, giving you fine-grained control over outbound network access. Access lists are configured at three levels, harness, agent, and session, and each layer can only make access *more* restrictive, never less. ## Configuration A network access list has two fields: | Field | Purpose | Default | | --------- | ---------------------------------------------- | --------------------- | | `allowed` | If non-empty, only matching URLs are permitted | `[]` (no restriction) | | `blocked` | Always denied, even if matched by `allowed` | `[]` | ### Pattern Format Patterns support three formats: | Format | Example | Matches | | --------------- | ----------------------------- | ------------------------------ | | Exact domain | `api.example.com` | Any URL on that exact domain | | Wildcard domain | `*.example.com` | The domain and all subdomains | | URL prefix | `https://api.example.com/v1/` | URLs starting with that prefix | Domain matching is case-insensitive. Blocked patterns always take precedence over allowed patterns. ### API Examples Set a network access list when creating or updating an agent: ```json POST /v1/agents { "name": "Research Agent", "system_prompt": "You are a research assistant.", "network_access": { "allowed": ["*.github.com", "api.openai.com"], "blocked": ["evil.example.com"] } } ``` Restrict a specific session further: ```json POST /v1/sessions { "agent_id": "agent_...", "network_access": { "blocked": ["internal.corp"] } } ``` To clear a network access list on update, send an empty object: ```json PATCH /v1/agents/{id} { "network_access": {} } ``` ## Layer Merging Network access lists merge across three layers using restrictive semantics, each layer can only narrow what the parent allows: ```plaintext Harness (baseline) ∩ Agent (can only restrict further) ∩ Session (can only restrict further) ``` The merge rules: | Field | Rule | Rationale | | --------- | ------------------------------------------------------------------------ | ------------------------------------------------- | | `allowed` | **Intersection**: child entries kept only if covered by a parent pattern | Child cannot grant access the parent didn’t allow | | `blocked` | **Union**: all blocked patterns combined | Child cannot un-block a parent’s block | If a child layer doesn’t set `allowed`, it inherits the parent’s list unchanged. ### Example Given this configuration: ```plaintext Harness: allowed: ["*.github.com", "*.openai.com"] Agent: allowed: ["api.github.com"], blocked: ["evil.com"] Session: blocked: ["malware.github.com"] ``` The effective policy for the session is: * **Allowed**: `["api.github.com"]`, kept because it’s a subset of `*.github.com`; `*.openai.com` dropped because the agent didn’t include it * **Blocked**: `["evil.com", "malware.github.com"]`, union of all layers Only `api.github.com` is reachable, and both `evil.com` and `malware.github.com` are explicitly denied. ### Harness Inheritance If a harness inherits from a parent harness (via `parent_harness_id`), the network access list is merged through the inheritance chain before any agent or session layer is applied. The same intersection/union rules apply. ## Enforcement The merged network access list is checked in `web_fetch` before every HTTP request. If a URL doesn’t match the effective policy, the tool returns an error: ```plaintext URL blocked by network access policy: https://blocked-domain.com/path ``` Standard SSRF protections (blocking private IPs, loopback, cloud metadata endpoints) are always enforced regardless of the network access list. ## Capabilities Affected | Capability | Enforced | Notes | | --------------- | -------- | --------------------------------------------- | | `web_fetch` | Yes | Checked before every HTTP request | | `bashkit_shell` | N/A | No network builtins (curl/wget not available) | --- # Physical Architecture > The physical components that make up an Everruns deployment, control plane, workers, PostgreSQL, NATS JetStream, Valkey, and the reverse proxy, and how they fit together. Source: The [getting-started architecture](https://docs.everruns.com/getting-started/architecture/) page describes the *logical* shape of Everruns: a control plane, a worker tier, and a shared database. This page goes one level deeper and describes the *physical* components an operator actually deploys, what each one is for, when it is optional, and how data flows between them. ![Physical Architecture](https://docs.everruns.com/_astro/physical-architecture.imwAYMfQ_HhXX7.svg) ## Components at a glance | Component | Role | Required | Default port | | ---------------------- | -------------------------------------------------------------------------- | --------------------------- | ------------------------ | | Reverse proxy | TLS termination and route fan-out for `/api`, `/mcp`, `/.well-known/*`, UI | Yes (or equivalent ingress) | 443 | | Control plane (server) | REST API, SSE event streams, gRPC server for workers, owns all state | Yes | 9301 (HTTP), 9001 (gRPC) | | Worker pool | Stateless executors of the agentic loop (input → reason → act) | Yes | , (outbound only) | | PostgreSQL 17 | Durable storage for agents, sessions, events, durable task queue | Yes | 5432 | | NATS JetStream | Push-based ephemeral event delivery and task notifications | Optional | 4222 | | Valkey | Distributed sliding-window rate limiting across control-plane instances | Optional | 6379 | | Management UI | Operator interface for agent and provider configuration | Optional | , (served by proxy) | Workers never talk to PostgreSQL, NATS, or Valkey directly. Every read and write goes through the control plane’s gRPC service on port 9001. This is what lets workers run with no database credentials, no encryption keys, and no awareness of the data tier. ## PostgreSQL, the only required stateful component PostgreSQL is the single source of truth for everything Everruns persists. There is no in-memory cache that needs warming, no secondary store that needs syncing, and no analytics database to keep consistent. If you back up PostgreSQL, you back up the entire system. What lives in PostgreSQL: * Agents, sessions, messages, and durable events * The durable task queue used by the worker tier (claimed via `SKIP LOCKED`) * Encrypted LLM provider credentials, MCP server registrations, capability config * Per-session virtual filesystems, knowledge bases, and the event log used for SSE replay Operational requirements: * **PostgreSQL 17.** UUIDv7 is implemented via a custom SQL function; PG 18’s native `uuidv7()` will be adopted once it is widely available on managed services. * **Direct connection for `LISTEN/NOTIFY`.** Pooled or proxied endpoints (PgBouncer, Neon `-pooler`, RDS Proxy) interleave notification frames with query traffic. Set `DATABASE_URL` to the pooled endpoint for normal queries and `DATABASE_UNPOOLED_URL` to a direct session-scoped endpoint for listeners. Startup fails fast if the configured listener URL looks pooled. * **Pool sizing.** With `EXPECTED_INSTANCES=N` set, each instance sizes its pool so that `pool × instances` stays under 80% of `PG_MAX_CONNECTIONS`. * **Migrations.** Auto-applied on server startup via embedded sqlx migrations, protected by a PostgreSQL advisory lock so multiple control-plane instances can boot together without racing. See [`docs/sre/environment-variables.md`](https://docs.everruns.com/sre/environment-variables/) for the full list of database-related variables. ## NATS JetStream, optional push delivery NATS is not required, but turning it on materially reduces PostgreSQL write pressure and SSE tail latency for busy deployments. Without NATS, Everruns uses PostgreSQL for both storage *and* delivery: ephemeral events persist to PG and SSE clients poll PG with `LISTEN/NOTIFY` wakeups; workers are notified of new tasks the same way. This works, and it is the default. The cost is write amplification, every streaming-token delta lands in PG even though no client will ever re-read it. With `NATS_URL` set and JetStream enabled, Everruns rewires two hot paths: * **Ephemeral event delivery.** Delta events (`output.message.delta`, `reason.thinking.delta`, `tool.output.delta`, `llm.generation`) skip PostgreSQL entirely and flow only through NATS JetStream. SSE streams subscribe to per-session subjects with short-term retention. Durable events (`output.message.completed`, `turn.started`, `tool.completed`, etc.) still persist to PG so SSE reconnection via `since_id` continues to work, missed deltas are acceptable because the completed event carries the full content. * **Task notifications.** `task.available.{activity_type}` subjects replace PG NOTIFY for worker wakeup, dropping notification latency from \~30 ms to \~1 ms. NATS is fail-graceful: if the connection fails at startup, the control plane logs a warning and falls back to the PG-backed paths. Only the control plane connects to NATS, workers still talk to the server via gRPC. ## Valkey, optional distributed rate limiting Valkey is a Redis-compatible key-value store (a Linux Foundation fork of Redis). Everruns uses it for exactly one thing: sliding-window rate limiting that is coordinated across control-plane instances. When `VALKEY_URL` is not set, rate limiting falls back to an in-memory governor, accurate per-instance, but with N instances behind a load balancer a single IP can consume up to N× the intended budget. Set `VALKEY_URL` when you run more than one control-plane instance and need a shared budget. Connection details: * Accepts `redis://`, `rediss://` (TLS), `valkey://`, `valkeys://` (TLS) schemes * Uses atomic Lua scripts for sliding-window counters * **Fail-open:** if Valkey is unreachable, the rate limiter allows the request rather than rejecting traffic on a side-channel outage * Only the control plane connects to Valkey; workers do not need access ## Worker pool, no shared state Workers are the most operationally boring component in the deployment. They have: * No database connection * No encryption key * No NATS or Valkey access * No durable local state They claim a task from the control plane over gRPC, fetch the turn context in a single batched call, run the agentic loop (LLM calls, tool execution), and stream events back. If a worker crashes mid-task, the heartbeat stops, the control plane reclaims the task after 30 seconds, and another worker picks it up. Add workers for throughput; remove them to save cost. See [Worker authentication](https://docs.everruns.com/sre/runbooks/durable-mode-setup/) for the `WORKER_GRPC_AUTH_TOKEN` and optional mTLS setup that secures this internal channel. ## Reverse proxy contract A reverse proxy (or platform ingress that enforces the same routes) is mandatory in production: | Route | Destination | Notes | | ---------------- | ------------- | ----------------------------------- | | `/api/*` | Control plane | Disable proxy buffering for SSE | | `/mcp` | Control plane | Do **not** rewrite under `/api` | | `/.well-known/*` | Control plane | OAuth discovery; do **not** rewrite | | `/health` | Control plane | Health check target | | Everything else | UI | If UI is deployed; otherwise 404 | TLS terminates at the proxy. Worker gRPC traffic stays on the private network, never expose port 9001 publicly. See [`local/Caddyfile`](https://github.com/everruns/everruns/blob/main/local/Caddyfile) and [`examples/docker-compose-full.yaml`](https://github.com/everruns/everruns/blob/main/examples/docker-compose-full.yaml) for working configurations. ## Development modes The same binaries collapse into smaller deployments for local work: * **`DEV_MODE=true` (in-memory).** No PostgreSQL, no Docker. Execution runs in-process inside the server binary; the gRPC server is disabled. Data is lost on restart. Useful for UI iteration and API development. * **`just start-all` (full local).** Brings up PostgreSQL, Valkey, and NATS as local processes (no Docker required) and starts the server + worker against them. Mirrors production wiring on a single machine. * **Docker Compose.** The production-shaped topology in one machine; see [Docker Compose](https://docs.everruns.com/getting-started/docker-compose/). ## Multi-instance deployment Multiple control-plane instances can run behind a load balancer with no session affinity: | Concern | How it stays correct | | -------------------- | ----------------------------------------------------------------------------------------- | | Database connections | `EXPECTED_INSTANCES=N` divides the pool so `pool × instances ≤ 80% of PG_MAX_CONNECTIONS` | | SSE delivery | `LISTEN/NOTIFY` or NATS subjects fan out to every instance; reconnects are idempotent | | Task claiming | `SKIP LOCKED` on the durable task queue partitions work naturally | | Migrations | PostgreSQL advisory lock prevents concurrent runs | | Rate limits | Valkey-backed sliding-window counters are shared; in-memory falls back to per-instance | Workers do not require coordination, add as many as you need, in as many regions as you need, as long as they can reach the control-plane gRPC port. ## Further reading * [Architecture (Getting Started)](https://docs.everruns.com/getting-started/architecture/), the logical model * [Environment Variables](https://docs.everruns.com/sre/environment-variables/), every knob and its default * [Docker Compose](https://docs.everruns.com/getting-started/docker-compose/), a production-shaped local setup * [Custom backends](https://docs.everruns.com/framework/custom-backends/), low-level execution-host composition --- # Read Tools > Parameters, pagination, content-type defaults, and exec output retrieval for the read-category tools. Source: Agents spend most of their context window on tool results. A single `cat` of a large file can consume thousands of tokens that crowd out reasoning space. The read-category tools are built to return the part the agent asked for and nothing else. Three tools form the read category: | Tool | Purpose | | ---------------- | ---------------------------------------------------------------------------------- | | `read_file` | Read file content with offset/limit pagination and line numbers | | `grep_files` | Search file contents by regex — returns matching lines with paths and line numbers | | `list_directory` | List files and directories with metadata (size, type) | Together they implement a **search → locate → read** workflow: `grep_files` finds where something is, `read_file` reads the relevant section, and `list_directory` provides structural context. ## read\_file ### Parameters | Parameter | Type | Default | Description | | --------- | ------- | ------------ | --------------------------------------------------- | | `path` | string | *(required)* | Absolute file path (e.g., `/workspace/src/main.rs`) | | `offset` | integer | 0 | Starting line number (0-indexed) | | `limit` | integer | 2000 | Maximum lines to return | ### Response ```json { "path": "/workspace/src/main.rs", "content": "1|use std::io;\n2|use serde::Serialize;\n3|\n4|fn main() {\n...", "total_lines": 450, "lines_shown": { "start": 1, "end": 450 }, "truncated": false, "content_type": "source", "read_mode": "offset", "size_bytes": 12480, "content_hash": "sha256:a1b2c3..." } ``` Key response fields: * **`content`** — Line-numbered output in compact `N|content` format. The `N|` prefix uses minimal bytes while giving agents precise line references for edits. * **`total_lines`** — Total lines in the file. Use this to know if more content exists beyond the current window. * **`lines_shown`** — 1-based start/end of the returned window. * **`truncated`** — `true` if more content exists beyond the returned window. * **`content_type`** — Detected content type (e.g., `log`, `csv`, `minified`, `source`). Reflects the heuristic applied. * **`read_mode`** — `tail` when reading log files from the end; `offset` otherwise. * **`content_hash`** — SHA-256 hash of the file content, used by `edit_file` for compare-and-set safety. ### Content-Type Defaults When the agent doesn’t specify `offset` or `limit`, `read_file` adjusts defaults based on file extension: | Content Type | Extensions | Default Limit | Read Mode | Rationale | | ------------ | --------------------------------- | ------------- | ------------------- | ------------------------------------------------------ | | Source code | `.rs`, `.ts`, `.js`, `.py`, etc. | 2000 lines | From offset | Standard — agent usually needs context around a region | | Log files | `.log`, `.out` | 500 lines | **From end (tail)** | Errors cluster at the end — recent output matters most | | CSV/TSV data | `.csv`, `.tsv` | 100 lines | From offset | Schema + sample rows; header always included | | Config | `.json`, `.yaml`, `.yml`, `.toml` | 2000 lines | From offset | Usually need full structure | | Minified | `.min.js`, `.min.css` | 20 lines | From offset | Single-line files would blow token budgets | | Text | `.md`, `.txt`, `.rst` | 2000 lines | From offset | Standard | **Explicit parameters override only the defaults they control.** An explicit `limit` overrides the content-type default limit. An explicit `offset` does **not** change the default limit by itself; it only controls where reading starts, and for log files it disables the default tail-biased read mode in favor of reading from that offset. If both `offset` and `limit` are provided, both behaviors are explicitly controlled. For CSV files, the header row (line 1) is always included in the response, even when reading with an offset. This ensures the agent always has column names for context. ### Image and Binary Handling * **Images** (`.png`, `.jpg`, `.gif`, `.webp`) are returned as **native image content blocks**, not text. The agent sees the image directly. * **Binary files** (base64-encoded) are returned with `"encoding": "base64"` and no line formatting. * A **hard byte cap** (50 KB) acts as a safety net for pathological files like minified bundles. ## Pagination For files larger than the default window, page through with `offset` and `limit`: ```json // First read — gets lines 1-2000 { "path": "/workspace/big_file.rs" } // Response shows total_lines: 5000, truncated: true // Continue reading: { "path": "/workspace/big_file.rs", "offset": 2000, "limit": 2000 } // Gets lines 2001-4000. Continue until truncated: false. ``` The 2000-line default covers most source files entirely in a single read. For the rare cases where files are larger, the `total_lines` field tells the agent exactly how much remains. ## Keeping read results small The system prompt guides agents toward efficient reading patterns: 1. **Search before read** — Use `grep_files` to find relevant lines, then `read_file` with a targeted `offset` around the match. This avoids reading thousands of irrelevant lines. 2. **Don’t re-read** — Files already in conversation context don’t need to be read again. The agent should reference prior reads. 3. **Check `total_lines`** — When a read is truncated, the agent knows how much remains and can decide whether to continue or search within the unread portion. 4. **Use offset to continue** — After a truncated read, use `offset` to pick up where the previous read left off. ## Exec Output as Readable Files When sandbox tools (`bash`, `daytona_exec`, `e2b_exec`, etc.) produce output, the inline result is truncated based on the `output` verbosity parameter (default: `concise` \~2 KiB). But the **full output is always persisted** to the session filesystem. ### How It Works The `tool_output_persistence` capability (included in the Generic harness) writes full output before truncation: * **stdout** → `/.outputs/{tool_call_id}.stdout` * **stderr** → `/.outputs/{tool_call_id}.stderr` The truncated inline result includes metadata pointing to the persisted files: ```json { "stdout": "[truncated to 2 KiB — full output saved]", "stderr": "", "exit_code": 0, "success": true, "full_output": "/.outputs/call_abc123.stdout", "total_lines": 8450, "output_files": [ "/.outputs/call_abc123.stdout", "/.outputs/call_abc123.stderr" ] } ``` The agent can then `read_file` the persisted output selectively: ```json // Read last 100 lines of build output { "path": "/.outputs/call_abc123.stdout", "offset": 8350, "limit": 100 } ``` ### Priority-Aware Truncation When output is truncated, the system preserves error-relevant content. Lines matching error patterns (`error`, `Error`, `FAILED`, `panicked`, stack traces) are prioritized over noise like `Compiling...` or `Downloading...`. This means the inline 2 KiB concise output is more likely to contain the diagnostically useful parts. ### Output Verbosity Modes All exec tools accept an `output` parameter: | Mode | Budget | Use case | | --------- | --------- | ---------------------------------- | | `silent` | \~200 B | Fire-and-forget commands | | `concise` | \~2 KiB | Builds, installs (**default**) | | `normal` | \~8 KiB | General debugging | | `verbose` | \~16 KiB | Test failures, error investigation | | `full` | unlimited | When the agent needs every line | ## Content Hash and Edit Safety Every `read_file` response includes a `content_hash` (SHA-256). The `edit_file` tool requires this hash via its `expected_hash` parameter — if the file has changed since the read, the edit is rejected. This **compare-and-set** mechanism prevents stale edits in long conversations where the agent may have read a file many turns ago and the file has since been modified (by another tool call or external process). ```json // read_file returns content_hash { "content_hash": "sha256:a1b2c3..." } // edit_file uses it as expected_hash — rejected if file changed { "path": "/workspace/src/main.rs", "expected_hash": "sha256:a1b2c3...", "old_text": "fn main() {", "new_text": "fn main() -> Result<()> {" } ``` If an edit is rejected due to a stale hash, the agent should re-read the file to get the current content and hash, then retry the edit. ## Structural Outlines When `read_file` returns a truncated result, the response includes a **structural outline** of the unread portions — function/class/method signatures without bodies. The agent can orient itself in any file with a single partial read. ```plaintext 1|use std::collections::HashMap; 2|use serde::Serialize; ... (lines read normally) ... 100| let result = process(&input); --- Outline of lines 101-500 (not shown) --- // L105: fn process(input: &Input) -> Result { ... } // L180: fn validate(output: &Output) -> bool { ... } // L220: struct Config { ... } // L235: impl Config { ... } // L236: fn load(path: &str) -> Result { ... } // L270: fn merge(&mut self, other: &Config) { ... } // L310: #[cfg(test)] mod tests { ... } ``` ### Supported Languages | Language | Extensions | | ---------- | ----------------------------- | | Rust | `.rs` | | TypeScript | `.ts`, `.tsx`, `.mts` | | JavaScript | `.js`, `.jsx`, `.mjs`, `.cjs` | | Python | `.py` | ### What Gets Outlined * **Functions/methods** — name, parameters, return type * **Structs/classes/enums** — name * **Impl blocks / trait implementations** — with nested methods * **Modules** — including `#[cfg(test)]` detection * **Interfaces and type aliases** (TypeScript) For unsupported languages, no outline is generated — the response still works, just without structural context for unread portions. --- # Request Signing > How Everruns signs outbound HTTP requests with Ed25519 signatures per RFC 9421, enabling target servers to verify bot identity Source: When an AI agent fetches web content, the receiving server has no way to distinguish it from an anonymous scraper. **Request signing** solves this by attaching a cryptographic signature to every outbound HTTP request, letting target servers verify who is making the request and choose to grant or deny access based on that identity. Everruns implements the [Web Bot Authentication Architecture](https://datatracker.ietf.org/doc/html/draft-meunier-web-bot-auth-architecture) (draft-meunier) using Ed25519 signatures over [RFC 9421 HTTP Message Signatures](https://www.rfc-editor.org/rfc/rfc9421). ## Background ### The Problem Traditional bot identification relies on `User-Agent` strings, which are trivially spoofed. IP-based allow lists are brittle and don’t scale. There is no standard way for a web bot to prove its identity to a server. ### HTTP Message Signatures (RFC 9421) RFC 9421 defines a general mechanism for signing HTTP messages. A sender selects components of the request (method, authority, specific headers) and signs them with a private key. The signature and a description of what was signed are transmitted as structured headers: ```plaintext Signature: sig=:base64url-encoded-signature: Signature-Input: sig=("@authority");created=1735689600;expires=1735689900; keyid="JWK-thumbprint";alg="ed25519";nonce="random"; tag="web-bot-auth" ``` The receiving server reconstructs the same signature base from the request, fetches the sender’s public key, and verifies the signature. Replay attacks are prevented by the `created`/`expires` window and random `nonce`. ### Web Bot Authentication Architecture The [draft-meunier-web-bot-auth-architecture](https://datatracker.ietf.org/doc/html/draft-meunier-web-bot-auth-architecture) builds on RFC 9421 specifically for bot identification: * **Algorithm**: Ed25519 (fast, small keys, no parameter choices) * **Covered components**: `@authority` (the target domain) at minimum * **Key identity**: [JWK Thumbprint](https://www.rfc-editor.org/rfc/rfc7638) (SHA-256 hash of the canonical public key representation) * **Signature tag**: `"web-bot-auth"`, distinguishes bot-auth signatures from other uses of RFC 9421 * **Discovery**: optional `Signature-Agent` header points to a FQDN where the bot’s public keys can be found ### Key Discovery The companion [draft-meunier-http-message-signatures-directory](https://datatracker.ietf.org/doc/html/draft-meunier-http-message-signatures-directory) defines how target servers find a bot’s public keys: ```plaintext GET https:///.well-known/http-message-signatures-directory ``` This returns a [JSON Web Key Set (JWKS)](https://www.rfc-editor.org/rfc/rfc7517#section-5) containing the bot’s Ed25519 public keys. The target server uses the `kid` field to match the key against the `keyid` in the incoming signature. ![Request Signing Flow](https://docs.everruns.com/_astro/request-signing-flow.CTmPi6LM_WOQ84.svg) ## How It Works in Everruns Request signing is implemented as a server-wide feature. When enabled, **every outbound HTTP request** made by the `web_fetch` tool is signed. ### Signing (outbound) The signing pipeline is handled by [fetchkit](https://github.com/everruns/fetchkit), the library powering the `web_fetch` capability: 1. Agent calls `web_fetch` with a URL 2. fetchkit builds the HTTP request 3. If bot-auth is configured, fetchkit signs the request: * Covers `@authority` and optionally `signature-agent` * Generates a random nonce * Sets `created` and `expires` timestamps * Signs with Ed25519, attaches `Signature` and `Signature-Input` headers 4. If signing fails (clock error, etc.), the request proceeds unsigned with a warning logged, signing never blocks requests 5. The request is sent to the target server ### Key directory (inbound) Everruns serves the public key at `/.well-known/http-message-signatures-directory`. This endpoint: * Is **public** (no authentication required) * Returns a JWKS containing the server’s Ed25519 public key * Derives the key at startup from the same seed used for signing Example response: ```json { "keys": [ { "kty": "OKP", "crv": "Ed25519", "x": "base64url-encoded-public-key", "kid": "JWK-thumbprint-matching-keyid-in-signatures" } ] } ``` ### What target servers see A signed request arrives with three additional headers: | Header | Purpose | | ----------------- | --------------------------------------------------------------------------- | | `Signature` | The Ed25519 signature over the covered components | | `Signature-Input` | Describes what was signed: components, timestamps, key ID, algorithm, nonce | | `Signature-Agent` | FQDN where the bot’s public keys can be discovered (optional) | Target servers that support web-bot-auth can: 1. Extract the `keyid` from `Signature-Input` 2. Fetch the public key from the `Signature-Agent` FQDN’s well-known endpoint 3. Verify the signature 4. Apply access policies based on the verified identity Servers that don’t support it simply ignore the extra headers. ## Verifying Signatures (Server Side) If you operate a server that receives requests from Everruns agents, here’s how to verify them. ### Verification steps 1. **Check the tag**: parse `Signature-Input` and confirm `tag="web-bot-auth"`. Ignore signatures with other tags. 2. **Check timestamps**: reject if `created` is in the future or `expires` is in the past. A 5-minute clock skew tolerance is reasonable. 3. **Fetch the public key**: extract the `Signature-Agent` FQDN and fetch `https:///.well-known/http-message-signatures-directory`. Find the key matching the `keyid` from `Signature-Input`. Cache the JWKS (keys rotate infrequently). 4. **Reconstruct the signature base**: build the canonical representation per [RFC 9421 Section 2.5](https://www.rfc-editor.org/rfc/rfc9421#section-2.5) using the covered components listed in `Signature-Input`. 5. **Verify**: use Ed25519 to verify the signature against the reconstructed base and the fetched public key. ### Python example ```python import base64 import hashlib import time import httpx from cryptography.hazmat.primitives.asymmetric.ed25519 import Ed25519PublicKey def verify_bot_auth(request) -> bool: """Verify a web-bot-auth signature on an incoming request.""" # 1. Parse Signature-Input header sig_input = request.headers.get("signature-input", "") if 'tag="web-bot-auth"' not in sig_input: return False # not a bot-auth signature # Extract parameters from sig_input # sig=("@authority" "signature-agent");created=...;expires=...;keyid="...";... params = parse_signature_params(sig_input) # 2. Check timestamps now = int(time.time()) if params["created"] > now + 300 or params["expires"] < now: return False # expired or future-dated # 3. Fetch public key from Signature-Agent FQDN agent_fqdn = request.headers.get("signature-agent", "") jwks_url = f"https://{agent_fqdn}/.well-known/http-message-signatures-directory" jwks = httpx.get(jwks_url).json() key_data = next(k for k in jwks["keys"] if k.get("kid") == params["keyid"]) public_key_bytes = base64.urlsafe_b64decode(key_data["x"] + "==") public_key = Ed25519PublicKey.from_public_bytes(public_key_bytes) # 4. Reconstruct signature base (RFC 9421 Section 2.5) # Covered components are listed in parentheses in Signature-Input sig_base = build_signature_base(request, params) # 5. Verify signature = base64.b64decode( request.headers["signature"].split(":")[1] # sig=:base64: ) try: public_key.verify(signature, sig_base.encode()) return True except Exception: return False ``` ### Node.js example ```javascript import { createPublicKey, verify } from "node:crypto"; async function verifyBotAuth(request) { const sigInput = request.headers["signature-input"] || ""; if (!sigInput.includes('tag="web-bot-auth"')) return false; const params = parseSignatureParams(sigInput); // Check timestamps (5-minute tolerance) const now = Math.floor(Date.now() / 1000); if (params.created > now + 300 || params.expires < now) return false; // Fetch public key const fqdn = request.headers["signature-agent"]; const res = await fetch( `https://${fqdn}/.well-known/http-message-signatures-directory` ); const jwks = await res.json(); const jwk = jwks.keys.find((k) => k.kid === params.keyid); const key = createPublicKey({ key: jwk, format: "jwk" }); // Reconstruct signature base and verify const sigBase = buildSignatureBase(request, params); const signature = Buffer.from( request.headers["signature"].split(":")[1], "base64" ); return verify(null, Buffer.from(sigBase), key, signature); } ``` > **Note:** The `parseSignatureParams` and `buildSignatureBase` helpers follow the structured fields parsing rules from [RFC 8941](https://www.rfc-editor.org/rfc/rfc8941) and the signature base construction from [RFC 9421 Section 2.5](https://www.rfc-editor.org/rfc/rfc9421#section-2.5). Libraries like [httpbis-message-signatures](https://pypi.org/project/httpbis-message-signatures/) (Python) and [@httpbis/message-signatures](https://www.npmjs.com/package/@httpbis/message-signatures) (Node.js) handle both. ## Configuration Request signing is configured via environment variables. Set them before starting the server. ### Environment variables | Variable | Required | Default | Description | | --------------------------- | -------- | ------- | -------------------------------------- | | `BOT_AUTH_SIGNING_KEY_SEED` | yes | , | Base64url-encoded 32-byte Ed25519 seed | | `BOT_AUTH_AGENT_FQDN` | no | , | FQDN for the `Signature-Agent` header | | `BOT_AUTH_VALIDITY_SECS` | no | `300` | Signature validity window in seconds | When `BOT_AUTH_SIGNING_KEY_SEED` is not set, signing is disabled and no crypto code runs at request time. ### Generate a signing key ```bash python3 -c "import os, base64; print(base64.urlsafe_b64encode(os.urandom(32)).rstrip(b'=').decode())" ``` ### Enable signing ```bash export BOT_AUTH_SIGNING_KEY_SEED="your-base64url-seed-here" export BOT_AUTH_AGENT_FQDN="bot.yourcompany.com" ``` Then start the server. All `web_fetch` requests will be signed, and the public key will be available at `https://bot.yourcompany.com/.well-known/http-message-signatures-directory`. ### Verify it’s working ```bash # Check the key directory endpoint curl -s http://localhost:9301/.well-known/http-message-signatures-directory | jq . ``` ## Standards | Standard | Role | | ---------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------- | | [RFC 9421, HTTP Message Signatures](https://www.rfc-editor.org/rfc/rfc9421) | Core signing mechanism, how to sign and verify HTTP requests | | [RFC 8941, Structured Field Values](https://www.rfc-editor.org/rfc/rfc8941) | Encoding format for `Signature` and `Signature-Input` headers | | [RFC 7638, JWK Thumbprint](https://www.rfc-editor.org/rfc/rfc7638) | How the `keyid` is computed from the public key | | [RFC 7517, JSON Web Key (JWK)](https://www.rfc-editor.org/rfc/rfc7517) | Format of the keys in the JWKS response | | [RFC 8037, Ed25519 in JOSE](https://www.rfc-editor.org/rfc/rfc8037) | Ed25519 key representation in JWK format | | [draft-meunier-web-bot-auth-architecture](https://datatracker.ietf.org/doc/html/draft-meunier-web-bot-auth-architecture) | Bot-specific profile of RFC 9421 (algorithm, tag, covered components) | | [draft-meunier-http-message-signatures-directory](https://datatracker.ietf.org/doc/html/draft-meunier-http-message-signatures-directory) | Well-known endpoint for public key discovery | ## See Also * [fetchkit](https://github.com/everruns/fetchkit), The library implementing the signing client --- # Tool Output Pipeline > How Everruns processes tool results from execution to the model, verbosity budgets, distillation, persistence, hard limits, and where the full output lives Source: Agents generate most of their context from **tool output**: shell commands, file reads, web fetches, SQL queries, and MCP tool calls. Left unmanaged, a single verbose command (`git diff`, a 10,000-row query, an installer log) can blow past the model’s context window, drive up cost, and bury the signal the agent actually needs. Everruns runs every tool result through a **multi-stage pipeline** that shrinks what the model sees while keeping the full original recoverable. This page explains each stage, the order they run in, and, crucially, *where the full output goes* so the agent can get it back. ## The big picture ```plaintext tool runs │ ▼ raw output ──────────────────────────────────────────────┐ │ │ (full, lossless) ▼ │ 1. Verbosity budget (exec/sandbox tools only) │ │ auto/concise/normal/verbose/full │ ▼ │ 2. Capability hooks │ │ • Tool Output Distillation (non-exec tools) │ ▼ ▼ 3. Final infrastructure hooks /outputs/ │ • Persist Output (exec tools → VFS) {tool_call_id}.stdout │ • Output Hard Limit (64 KiB ceiling) {tool_call_id}.stderr ▼ ▲ inline result → stored in the session, │ shown to the model next turn ──────────────────────┘ (read_file recovers the full original) ``` Two ideas run through the whole pipeline: 1. **Storage stays lossless.** Whatever the model sees inline, the full output is written to the session filesystem (the *destination*). The inline view always carries a pointer back to it. 2. **Each stage shrinks, none deletes.** Truncation, distillation, and masking only change the *view*. The agent can always `read_file` the persisted original. ## Stage 1, Verbosity budget (exec tools) Exec and sandbox tools (`bash`, `*_exec`, sandboxed shells) clean their output (strip ANSI, collapse carriage returns) and apply a **verbosity budget** before returning. The mode is configurable per call; the default is `auto`: * **Success (`exit_code == 0`)** → collapse to a compact summary (\~512 bytes), because the full log is persisted (Stage 3) and the agent rarely needs it inline. * **Failure (non-zero exit)** → keep a larger diagnostic window (\~8 KiB) so the error stays debuggable in-loop. The full pre-truncation output is stashed on the result as `raw_output` for the persistence hook to consume. Non-exec tools (MCP, web fetch, client tools) do **not** have a verbosity budget, that gap is what Stage 2 exists for. ## Stage 2, Tool Output Distillation (non-exec tools) [Tool Output Distillation](https://docs.everruns.com/capabilities/) targets the tools Stage 1 doesn’t: **MCP tools and `web_fetch`**, whose results otherwise enter history verbatim. It runs as a capability hook, so it executes *before* the final hooks. For a large non-exec result, distillation produces a compact, **content-aware** inline view: | Output shape | What you get inline | | ---------------- | ---------------------------------------------------------------------------- | | Large JSON array | Schema-preserving sample: the first few rows + `[… N more items elided …]` | | Long string | Head + tail window (both ends preserved), with a byte-elision marker | | Unified diff | A diffstat-style summary: file + hunk headers and `+added / -removed` counts | | Nested object | Each oversized field distilled; small fields untouched | Before it replaces anything, distillation **persists the full original** to the session filesystem (same destination as Stage 3) and injects a recovery pointer. If persistence fails, or the session has no filesystem, it restores the verbatim output rather than leave a lossy result the agent can’t recover. **Reversibility is never sacrificed.** Distillation is on by default in the **generic harness**. Every transform is deterministic, so identical output distills identically and the model provider’s prompt cache keeps hitting across turns. ## Stage 3, Persistence and the hard limit Two infrastructure hooks always run last, in order: 1. **Persist Output**: for tools that declare the `persist_output` hint (exec/sandbox), writes the full `raw_output` to the session VFS. When content is absent from the inline result, it adds a recovery pointer; complete inline results keep the retained file internal and do not invite a redundant read. It **skips** if a result already carries `output_files` (e.g. distillation already persisted it), so the two never double-write. 2. **Output Hard Limit**: a final, unremovable 64 KiB ceiling. By the time it runs, the result has usually already been budgeted or distilled, so it rarely fires; it’s a backstop against pathological cases. ## The destination, where full output lives Everything the pipeline elides is recoverable from the **session filesystem**: ```plaintext /outputs/{tool_call_id}.stdout ← full standard output /outputs/{tool_call_id}.stderr ← full standard error (when present) ``` When the inline result omits persisted content, it carries the recovery pointer in `output_files` and `full_output`, plus a human-readable note telling the model to use `read_file` (with `offset`/`limit`) for the missing detail. Complete inline output has no model-facing pointer. Persisted streams are capped at 1 MiB each. Deleting the session cascades and removes them. This is the key to aggressive shrinking: because the original is one `read_file` away, the inline view can be small without the agent losing the ability to drill in. ## How this relates to compaction The pipeline above operates on **individual tool results at capture time**. [Context Compaction](https://docs.everruns.com/advanced/compaction/) operates **later**, across the whole conversation, when it approaches the context window, masking or summarizing older messages at serialization time. They compose cleanly: * The pipeline keeps each result lean as it’s produced. * Compaction further masks older results when the *accumulated* history grows too large. * [Infinity Context](https://docs.everruns.com/capabilities/) adds a `query_history` tool to retrieve older *messages* that scrolled out of the window. Together: the pipeline controls per-result size, compaction controls total-history size, and both keep the full record recoverable. ## Summary | Stage | Applies to | Effect | Destination of full output | | ----------------- | -------------------------- | -------------------------------------------------------- | --------------------------------------------- | | Verbosity budget | exec/sandbox | Compact summary on success, diagnostic window on failure | `raw_output` → persisted in Stage 3 | | Distillation | MCP / web fetch / non-exec | Content-aware compact view | `/outputs/{id}.stdout` | | Persist Output | `persist_output` tools | Lossless write + pointer | `/outputs/{id}.{stdout,stderr}` | | Output Hard Limit | all | 64 KiB ceiling backstop | (already persisted) | The agent always sees a lean view and can always recover the full original with `read_file`. --- # Agent Checks > Advisory quality checks for agent configurations, structural problems, completeness gaps, and cost warnings surfaced while you build. Source: # Agent Checks Agent checks review an agent configuration and surface advisory findings while you build: structural problems (duplicated instructions, conflicting style guidance), completeness gaps (tool references that do not exist), and cost warnings (oversized prompts). Checks are advisory only. Findings never block saving, publishing, or version creation. ## Where Findings Appear * **Agent editor → Preview tab**: a Checks card lists findings for the current draft, updating as you edit. * **API**: `POST /v1/agents/preview` returns a `findings` array alongside the resolved system prompt and tools. * **MCP / platform commands**: the `preview_agent` and `analyze_agent` commands return the same findings, so agents and automations can review configurations programmatically. ## Findings Each finding includes: | Field | Description | | ---------- | --------------------------------------------------------------------------- | | `rule_id` | Stable rule identifier, e.g. `prompt.duplicate_paragraphs` | | `severity` | `warning`, `info`, or `suggestion`, there is no `error`; checks never block | | `category` | `structure`, `completeness`, `effectiveness`, `safety`, or `cost` | | `message` | Human-readable explanation | | `location` | The config field (and byte span, when applicable) the finding points at | ## AI Analysis The **Analyze** button on the Checks card runs a deeper on-demand review using the platform’s internal utility LLM (requires `UTILITY_OPENAI_API_KEY` or `UTILITY_OPENROUTER_API_KEY` on the deployment). Three scoped checkers run in parallel: | Rule | What it catches | | ------------------- | -------------------------------------------------------------------------------------------------------------- | | `llm.contradiction` | Instructions that cannot both be followed, including conflicts between the prompt and capability contributions | | `llm.structure` | Redundancy, verbosity, vague instructions, and structure that buries critical rules | | `llm.tool_guidance` | Prompt guidance that misdescribes available tools or assumes functionality no tool provides | LLM findings can carry a suggested replacement for the offending text; when the finding is anchored to a span of your prompt, an **Apply fix** button replaces it in place. Analysis is available via `POST /v1/agents/analyze`, which returns built-in and LLM findings merged. The reviewed prompt is treated strictly as data: checker outputs are bounded, severities are clamped, and findings are advisory text only. ## Health Checks A **health check** runs the agent for real. It generates a handful of smoke-test cases from the agent’s description, system prompt, and capabilities, runs each as an actual session against the agent’s configured model, and scores the result two ways: * **Deterministic**: the agent produced a non-empty answer and finished within a turn budget. * **AI judge**: the platform’s utility LLM grades the agent’s final response against a rubric generated for that case. A case passes only when both checks pass. The run surfaces a score card (pass rate, passed count, average score, average turns) and a per-case list, each case links to the real session so you can inspect the full conversation, tool calls, and events. Health checks are asynchronous (they run several real sessions and take a minute or two). Trigger one and poll for the result: | Method | Path | Description | | ------ | ---------------------------------------------- | -------------------------------------------------------------------- | | `POST` | `/v1/agents/{agent_id}/health-checks` | Start a run; returns a pending run with an `id` | | `GET` | `/v1/agents/{agent_id}/health-checks/{run_id}` | Poll the run; `status` goes `pending → running → completed`/`failed` | | `GET` | `/v1/agents/{agent_id}/health-checks` | List recent runs for the agent | Runs are stored per agent and keyed by the resolved config hash. Health checks require the utility LLM (`UTILITY_OPENAI_API_KEY` or `UTILITY_OPENROUTER_API_KEY`) to generate and judge cases, and the agent’s own model must be usable. They are advisory: a low score never blocks anything. ## Built-in Rules Checks run against the *resolved* configuration, after harness and capability contributions are merged, so they can catch issues that span layers. | Rule | Severity | What it catches | | ------------------------------ | -------- | ------------------------------------------------------------------------- | | `prompt.empty` | info | Agent has no system prompt of its own | | `prompt.very_long` | warning | Authored prompt over 32 KiB, sent on every model turn | | `prompt.resolved_very_long` | info | Full prompt over 96 KiB after harness/capability contributions | | `prompt.template_variables` | warning | `{{placeholder}}` text that would reach the model literally | | `prompt.duplicate_paragraphs` | warning | The same paragraph appears more than once | | `prompt.restates_contribution` | info | Prompt duplicates text already contributed by the harness or a capability | | `prompt.conflicting_style` | info | Asks for both brevity and detail without stating conditions | | `tools.unknown_reference` | info | Prompt references a tool that no enabled tool or capability provides | | `tools.duplicate_names` | warning | Two tools share a name, so the model cannot distinguish them | High-cardinality rules (`prompt.duplicate_paragraphs`, `tools.unknown_reference`, `tools.duplicate_names`) cap how many findings they emit. When the cap is exceeded they add a single companion `info` finding with the rule ID suffixed `.summary` (e.g. `prompt.duplicate_paragraphs.summary`) noting that only the first N were shown, so a large prompt cannot amplify into an unbounded response. ## Roadmap A later phase adds org-configurable rules: per-rule enable/severity settings for the built-ins plus custom declarative and natural-language-rubric rules. --- # AGENTS.md > The AGENTS.md capability resolves project-level instructions from workspace files hierarchically and injects them as the leading user message on every turn. Source: The **AGENTS.md** capability resolves project instruction files hierarchically — from the session filesystem root down to the working directory — and injects them as the leading user-role message on every turn. By default it reads `AGENTS.md`, Everruns’ implementation of the [`AGENTS.md`](https://agents.md/) open standard, an emerging convention backed by OpenAI, Google, Cursor, Sourcegraph, and the Linux Foundation. Workspace files are untrusted third-party content, so they never enter the system prompt: harness safety instructions always take precedence, and file edits never invalidate the cache-stable system prefix. When the capability is enabled: * The agent resolves `AGENTS.md` from the filesystem root down to the working directory on every turn by default. * A `docs/AGENTS.md` applies to work under `docs/`; deeper files override shallower ones on conflict. Files in sibling subtrees are never loaded. * Agents can configure `files` to resolve additional filenames such as `CLAUDE.md` at every hierarchy level. * Edits during a session apply on the next turn (no restart). * The assembled block opens with a trust framing header and renders each file in `` sections as the first user message — never as system prompt. * If a configured file doesn’t exist, the agent operates normally. ## Prompt order Every turn the model sees, top-to-bottom: 1. **System prompt**: harness safety instructions, tool guidance, role (cache-stable). 2. **Conversation context**: the resolved `AGENTS.md` hierarchy, broadest scope first — model-visible, re-resolved every turn, but below system instructions in precedence. 3. **Conversation history and the latest user message**. Explicit user instructions win over project files on conflict; system instructions always win over both. ## Limits * Content cap: **32 KiB per file** (excess truncated with a warning), plus a **128 KiB total budget** per turn binding hierarchy depth — deeper files past the budget are omitted with an explicit note. * Plain Markdown, no required sections. * At most 16 instruction files resolved per turn. ## Compatibility Everruns keeps `AGENTS.md` as the default. Configure the capability with `files` to read additional tool-specific files: ```json { "files": ["AGENTS.md", "CLAUDE.md"] } ``` ## Do something * [Use AGENTS.md for project instructions](https://docs.everruns.com/how-to/use-agents-md/), full guide with examples. * [Equip an agent with tools](https://docs.everruns.com/how-to/equip-agents-with-tools/), adding capabilities generally. ## See also * [AGENTS.md capability reference](https://docs.everruns.com/capabilities/agent-instructions/), config schema. --- # Agent Triggers > Run an agent proactively on a recurring schedule, choose session reuse, test it immediately, and inspect recent outcomes. Source: Agent triggers let an Agent start work on its own schedule. A trigger belongs to one Agent, runs on that Agent’s Harness, and sends a configured message when it fires. It does not require an inbound endpoint. Schedule triggers are the only trigger type currently available. ## Create a trigger in the UI 1. Open the agent. 2. Select the **Integrations** tab. 3. Select **Add trigger**. 4. Choose a preset or enter a 5-field cron expression (or a 7-field expression whose year is `*`), then enter an IANA timezone. The editor shows the schedule in human-readable form and previews the next eight runs. The default timezone is `UTC`. 5. Choose a session mode: * **Shared session** reuses one durable session for this trigger. Use it when later runs should see the trigger’s previous conversation. * **New session per run** creates a fresh session every time. Use it when each run should be isolated. 6. Enter the message that starts the run. Messages may use `{{...}}` template values from the agent, trigger, and invocation context. 7. Leave **Enabled** on to activate the schedule, then select **Create trigger**. The trigger card shows the schedule in human-readable form, its timezone, message, session mode, enabled state, and recent run outcomes. ## Operate and test a trigger From the **Triggers** section of the **Integrations** tab you can: * enable or disable the recurring schedule; * edit its schedule, timezone, session mode, message, or enabled state; * select **Run now** to start one invocation immediately; * inspect the most recent durable execution outcomes; or * delete the trigger. **Run now** uses the same execution path as a scheduled run. The trigger must be enabled. ## API Agent triggers are managed below `/v1/agents/{agent_id}/triggers`: | Method | Path | Purpose | | -------- | ----------------------------------------------------- | ------------------------- | | `GET` | `/v1/agents/{agent_id}/triggers` | List triggers | | `POST` | `/v1/agents/{agent_id}/triggers` | Create a schedule trigger | | `GET` | `/v1/agents/{agent_id}/triggers/{trigger_id}` | Get one trigger | | `PATCH` | `/v1/agents/{agent_id}/triggers/{trigger_id}` | Update provided fields | | `DELETE` | `/v1/agents/{agent_id}/triggers/{trigger_id}` | Delete a trigger | | `POST` | `/v1/agents/{agent_id}/triggers/{trigger_id}/trigger` | Run it now | | `GET` | `/v1/agents/{agent_id}/triggers/{trigger_id}/runs` | List recent outcomes | Create requests accept `cron_expression`, `timezone`, `session_mode`, `message`, and `enabled`. See the [API reference](https://docs.everruns.com/api/) for current request and response schemas. ## Migrated App Schedules The retired App model allowed `schedule` channels. Everruns migrated Agent-bound schedules to Agent triggers and preserved their cron expression, timezone, session mode, message, execution identity, and history. Agent triggers, webhook triggers, and session schedules solve different problems: * use an **agent trigger** when an agent should wake itself on a recurring schedule; * use a **webhook trigger** when an external HTTP request should invoke an Agent; and * use a **session schedule** when the current conversation should continue later. ## See also * [Slack Integration](https://docs.everruns.com/integrations/slack/), publish an Agent to an inbound messaging endpoint. * [Session participants](https://docs.everruns.com/features/session-participants/), understand the host agent used by a trigger-created session. * [API reference](https://docs.everruns.com/api/), exact trigger schemas and responses. --- # Agent Versions > Save immutable Agent snapshots, compare changes, roll back, and bind endpoints to a default, latest, or pinned version. Source: # Agent Versions Agent versions are saved snapshots of an agent configuration. They let you preserve a known-good prompt, tool, and capability setup while continuing to edit the draft agent. This feature is gated by `FEATURE_AGENT_VERSIONS`. ## What You Can Do * Save the current agent draft as a new version. * Set a default version for normal use. * Compare authored and resolved configuration between two versions. * Roll back the editable draft to a previous version. * Fork a version into a new agent. * Configure each endpoint to use the Agent default, latest version, or a pinned version. ## Runtime Behavior When a session is created, Everruns records the resolved `agent_version_id` on the session. Events emitted during that session include version metadata so logs, traces, and exports can identify the exact agent configuration that ran. Endpoints can use: * `default`: follow the agent default version. * `latest`: always use the newest saved version. * `pinned`: keep using a specific version until changed. ## Notes Versions are immutable. Rollback updates the editable draft and saves a new rollback version so history remains append-only. --- # Apps Compatibility > Understand the retired App model, permanent route compatibility, and the Agent-owned endpoint model that replaces it. Source: Apps are retired from Everruns management. New integrations belong directly to an Agent as **endpoints** or **triggers**. * Use an **endpoint** when an external peer sends a request and waits for a reply. Slack, AG-UI, A2A, FCP, and Public Chat use endpoints. * Use a **trigger** when a schedule or event starts Agent work without a reply channel. Create and manage both from the Agent’s **Integrations** tab. ![Agent Endpoint Architecture](https://docs.everruns.com/_astro/architecture.CISCOTZn_Z23yhDd.svg) ## Existing Apps Everruns keeps existing App records for historical attribution and compatibility. Existing installs continue to serve traffic, but the App list, detail page, create flow, and management API are retired. The old `/v1/apps/{app_id}/…` ingress paths remain permanent aliases. They resolve to the migrated endpoint and continue to work. Do not rewrite a working existing installation only to change its URL. New integrations use endpoint-scoped canonical paths: ```text /v1/e/{endpoint_id}/slack/events /v1/e/{endpoint_id}/ag-ui /v1/e/{endpoint_id}/a2a /v1/e/{endpoint_id}/fcp ``` ## Endpoint Lifecycle Each endpoint has its own lifecycle: ```text Draft ⇄ Live Draft → Disabled Live → Disabled Disabled → Draft ``` * **Draft**: Configured but does not accept ingress traffic. * **Live**: Published and able to accept traffic while its Agent is active and exposures are not suspended. * **Disabled**: Kept for configuration but rejects ingress traffic and does not invoke the Agent. Publishing or unpublishing one endpoint does not change another endpoint on the same Agent. ## Where to Go * [Slack Integration](https://docs.everruns.com/integrations/slack/), create and publish a Slack endpoint. * [Agent Triggers](https://docs.everruns.com/features/agent-triggers/), configure proactive scheduled work. * [Agent Versions](https://docs.everruns.com/features/agent-versions/), select which Agent version an endpoint uses. --- # Capabilities > Capabilities give an agent tools, system prompt fragments, and session state. Overview with links to the reference. Source: A **capability** is a self-contained unit that extends an agent. Each capability can contribute three kinds of thing: 1. **Tools**: functions the agent can invoke during a turn. 2. **System prompt additions**: text prepended to the agent’s prompt that teaches the model when and how to use those tools. 3. **Mount points**: files, directories, or session state the tools need to operate. Agents *compose* capabilities. Enable as many as you need; leave the rest disabled. The runtime resolves capabilities in topological order (dependencies first) and concatenates their system prompt fragments in the order you configured them on the agent. ## Why capabilities, not just tools A bare tool registration is a function with a JSON schema. Capabilities exist because real tools need more than that. To use `bashkit_shell` effectively, the agent needs both the `bash` tool *and* the prompt fragment explaining the sandbox model *and* the session filesystem (a dependency). Capabilities bundle those concerns into one enable/disable unit. See [Why capabilities are first-class](https://docs.everruns.com/explanation/concepts/#why-capabilities-are-first-class) for the full rationale. ## Where capabilities come from | Source | ID format | Example | | -------------- | -------------------- | ---------------------------------- | | Built-in | `snake_case` | `web_fetch`, `session_file_system` | | MCP server | `mcp:{uuid}` | `mcp:550e8400-...` | | Registry skill | `skill:{uuid}` | `skill:550e8400-...` | | Declarative | `declarative:{name}` | `declarative:research_pack` | All four kinds participate in the same merge, dependency resolution, and tool-name prefixing. The agent doesn’t care where a tool came from. ## Where to attach them Capabilities can be attached at three layers, and the layers stack additively: * **Harness**: defaults for every session that uses this harness. * **Agent**: capabilities for this specific role. * **Session**: extras for this one conversation. See [Why three configuration layers](https://docs.everruns.com/explanation/concepts/#why-three-configuration-layers-harness-agent-session) for how the merge works. ## Browse the catalog The full list of built-in capabilities, organised by category, lives in the reference: * **[Capabilities reference](https://docs.everruns.com/capabilities/)**: every capability with ID, tools, parameters, and dependencies. ## Do something * [Equip an agent with tools](https://docs.everruns.com/how-to/equip-agents-with-tools/), the practical recipe. * [Give an agent web access](https://docs.everruns.com/how-to/give-an-agent-web-access/), narrower task with network policies. * [Customize a harness](https://docs.everruns.com/how-to/customize-a-harness/), bundle capabilities at the harness layer. ## See also * [Concepts](https://docs.everruns.com/explanation/concepts/), the entity model in full. --- # CLI > Manage agents, sessions, and conversations from the command line. Source: The `everruns` CLI is a command-line client for the Everruns API. It covers the same surface as the SDK, agents, sessions, messages, capabilities, and is designed to compose well with shell pipelines. This page covers installation, configuration, and the command surface. For scripting patterns and `jq` examples, see [Automate with the CLI](https://docs.everruns.com/how-to/automate-with-the-cli/). ## Install ### Homebrew (macOS / Linux) ```bash brew tap everruns/tap brew install everruns ``` ### Cargo From the Git repository: ```bash cargo install --git https://github.com/everruns/everruns everruns-cli ``` Or clone and build: ```bash git clone https://github.com/everruns/everruns.git cd everruns cargo install --path crates/cli ``` ### Verify ```bash everruns --version ``` ## Configure The CLI defaults to the hosted API at `https://app.everruns.com/api`. Override for local or self-hosted deployments: ```bash # Per command everruns --api-url http://localhost:9300/api agents list # Per shell export EVERRUNS_API_URL=http://localhost:9300/api export EVERRUNS_API_KEY=dev ``` ## Command surface | Group | Subcommands | | -------------- | ------------------------------------------- | | `agents` | `create`, `list`, `get`, `update`, `delete` | | `sessions` | `create`, `list`, `get`, `cancel`, `delete` | | `capabilities` | (list, no subcommand) | | `chat` | Send a message and stream the response | ### Agents ```bash # Inline everruns agents create \ --name "my-agent" \ --system-prompt "You are a helpful assistant." \ --tag production # From a file (TOML, YAML, JSON, or Markdown front matter) everruns agents create -f agent.toml everruns agents create -f agent.yaml everruns agents create -f agent.md ``` If `./agent.toml` exists and you don’t pass inline flags, `everruns agents create` picks it up automatically. The file formats are documented in [Define agents as files](https://docs.everruns.com/how-to/define-agents-as-files/). ```bash everruns agents list everruns agents get agt_xxx everruns agents delete agt_xxx ``` ### Sessions ```bash everruns sessions create --agent agt_xxx everruns sessions create --agent agt_xxx --title "Debug session" # With session-level overrides everruns sessions create \ --agent agt_xxx \ --harness generic \ --capability 'web_fetch={"timeout":10}' \ --hint setup_connection=true \ --network-allow api.example.com \ --max-iterations 8 ``` Also accepts: `--locale`, repeatable `--tag`, `--system-prompt`, `--hints-json`, repeatable `--network-block`, repeatable `--secret KEY=VALUE`, and budget flags. ```bash everruns sessions list everruns sessions get ses_xxx ``` ### Chat ```bash everruns chat "Tell me a joke!" --session ses_xxx ``` Options: `--timeout ` (default 300), `--no-stream` to queue without waiting. ## Output formats Every command accepts `-o` / `--output`: ```bash everruns agents list -o json everruns agents list -o yaml ``` `--quiet` suppresses headers and prints only the essential identifier, useful for capturing IDs in shell variables. ## See also * [Automate with the CLI](https://docs.everruns.com/how-to/automate-with-the-cli/), `jq`, quiet mode, scripting patterns. * [Define agents as files](https://docs.everruns.com/how-to/define-agents-as-files/), file formats for `-f`. * [SDK](https://docs.everruns.com/features/sdk/), the programmatic equivalent. ## Agent composition Discover and manage the plugins, skills, and knowledge bases available to agents: ```bash # Plugins everruns plugins list everruns plugins get everruns plugins install everruns plugins uninstall # Skills everruns skills list everruns skills get everruns skills create ./SKILL.md everruns skills delete # Knowledge bases everruns knowledge-bases list everruns knowledge-bases get everruns knowledge-bases create "Product docs" --description "Published product documentation" everruns knowledge-bases delete ``` Resource identifiers are URL-encoded before requests are sent. Use the global `--output json` or `--output yaml` option for machine-readable discovery output. Skill creation reads the supplied Markdown file and sends its contents to Everruns. Knowledge document ingestion and assigning composition resources to an agent are not yet exposed by the CLI. --- # Evals > Define, run, and track behavioral tests for Agents. Each case runs a real session and is scored. Source: Evals let you define, run, and track **behavioral tests** for your Agents. An Eval is a named collection of cases; each case sends messages to a fresh session and scores the result. Use them to compare runs across models and catch regressions after a prompt change. Because every case runs a **real session** against the target agent and harness, failures are fully debuggable, click into the session to see the conversation, tool calls, and events exactly as they happened. ## Concepts | Entity | What it is | | -------------- | -------------------------------------------------------------------------------------------------------- | | **Eval** | Top-level, org-scoped collection of cases. Follows the standard `active → archived → deleted` lifecycle. | | **EvalCase** | A single test: input messages, scoring rules, execution bounds, and optional artifact collection. | | **EvalRun** | One execution of an eval’s cases against a target, producing per-case results. | | **EvalTarget** | How a session is instantiated from a Harness, Agent, model, and system prompt. | Targets resolve in order `EvalRun → EvalCase → Eval → org default harness`, so you can run the same cases against different models per run or override per case. ## How a case runs 1. A fresh session is created from the resolved target. 2. The case’s `conversation` messages are delivered sequentially (multi-turn supported). 3. Optional `post` messages run after the session idles, for example, executing a test script. 4. Optional `artifacts` capture named session files. 5. `scorers` grade the result, returning `0.0`–`1.0` for nuanced pass/fail. Eval runs are durable workflows: they reuse the same execution engine as production sessions, so a worker restart mid-run does not lose progress. ## SWE-bench Lite Beyond user-facing behavioral evals, Everruns ships a **SWE-bench Lite** harness for measuring coding-agent performance against the standard benchmark, using the same eval machinery (`post` verification messages run the test scripts that determine pass/fail). ## Related * [Harnesses](https://docs.everruns.com/features/harnesses/), what an eval target runs * [Agent Versions](https://docs.everruns.com/features/agent-versions/), immutable configurations that evals can compare --- # Events > SSE streaming of session events: categories, structure, and the wire protocol. Source: Every action during a session, user input, LLM responses, tool calls, lifecycle transitions, emits an **event**. The event log is the source of truth for session state; the SSE stream is a live tail of that log. For *why* the platform is shaped this way, see [Events as the primary store](https://docs.everruns.com/explanation/events/). For the full catalog of event types and payloads, see the [Event Reference](https://docs.everruns.com/event-reference/). ## Event categories | Category | Examples | Description | | ------------ | -------------------------------------------------------------------------------- | ----------------------------------------------------- | | **Input** | `input.message` | User messages submitted to the session | | **Output** | `output.message.started`, `output.message.delta`, `output.message.completed` | Agent response lifecycle | | **Turn** | `turn.started`, `turn.completed`, `turn.failed`, `turn.cancelled` | Turn lifecycle | | **Thinking** | `reason.thinking.*` | Extended thinking content (Claude, GPT-5.x, o-series) | | **Atom** | `reason.*`, `act.*`, `tool.*` | Internal execution phases | | **LLM** | `llm.generation` | Full LLM API call details | | **Session** | `session.started`, `session.activated`, `session.idled`, `session.model.changed` | Session state changes | | **Subagent** | `subagent.*` | Subagent lifecycle | ## Event structure ```json { "id": "event_01933b5a00007000800000000000001", "type": "turn.completed", "ts": "2024-01-15T10:30:00.000Z", "session_id": "session_01933b5a00007000800000000000002", "sequence": 42, "context": { "turn_id": "turn_...", "input_message_id": "message_...", "trace_id": "turn_...", "span_id": "abc123", "parent_span_id": "def456" }, "data": { /* type-specific payload */ } } ``` | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------- | | `id` | string | Unique event ID (UUIDv7) | | `type` | string | Event type in dot notation | | `ts` | string | ISO 8601 with millisecond precision | | `session_id` | string | Session this event belongs to | | `sequence` | integer | Monotonic per-session sequence (ordering source of truth) | | `context` | object | Correlation IDs for tracing | | `data` | object | Event-specific payload | Ordering is by `sequence`, not `ts`. Two events with the same wall-clock time still have a strict order. ## Common patterns ### Started → completed → failed Long-running operations follow a lifecycle: ```plaintext turn.started → turn.completed ↘ turn.failed ↘ turn.cancelled ``` These boundaries are what your UI uses to manage state and surface errors. ### Delta streaming Streaming content uses delta events with accumulated state: ```json { "type": "output.message.delta", "data": { "turn_id": "turn_...", "delta": "Hello", "accumulated": "Hello" } } ``` Deltas are batched at \~100ms to reduce volume. ## Forward-compatibility Events follow a defined contract. Consumers must tolerate evolution: | Change | Allowed | | --------------------------- | ------- | | New event types | yes | | New optional fields | yes | | New enum values | yes | | Removing or retyping fields | no | Your deserializer should ignore unknown fields, ignore unknown event types, and treat optional fields as optional. ## Consume the stream * [Stream events with the SDK](https://docs.everruns.com/how-to/stream-events/), the convenient path (Python, Rust, TypeScript). * [Consume events via raw SSE](https://docs.everruns.com/how-to/consume-events-via-sse/), protocol-level, when the SDK isn’t available. ## See also * [Event Reference](https://docs.everruns.com/event-reference/), complete event type catalog with payloads. * [Events as the primary store](https://docs.everruns.com/explanation/events/), design rationale. --- # Harnesses > A harness is what an agent runs on, the execution environment, default model, and bundled capabilities that agents and sessions extend. Source: A **harness** is what an agent *runs on*. It answers “what environment am I working in, and what is available to me?”, the execution environment, the default model, and a bundle of capabilities. Every session is assigned exactly one harness. Agents and sessions then layer their own configuration on top. The split that matters is **world versus behavior**: | | Answers | Owns | | ----------- | ----------------------------------------- | -------------------------------------------------------------------------------------- | | **Harness** | ”What am I running in?” | Execution environment, network access, capability bundle, default model, starter files | | **Agent** | ”What role am I playing?” | Instructions, domain capabilities, the agent’s voice | | **Session** | ”What is true for this one conversation?” | Per-conversation extras, overrides, a tighter network policy | A harness exists before any agent uses it, and many agents share one. ### Who points at a harness Both an agent and a session carry a harness reference: * Every **agent** holds exactly one `harness_id`. It is the harness that agent’s sessions run on by default. On create, an agent inherits the organization’s default harness unless you pass `harness_id` or `harness_name`; an explicit choice stays pinned. * A **session** may name its own harness and override the agent’s. Precedence when a session starts, first match wins: 1. The harness named on the session request 2. The agent’s harness 3. The organization default 4. The built-in fallback So the same agent can be run on a different harness for one session without editing the agent, while changing it for good means updating the agent. For the design rationale (why three configuration layers exist), see [Concepts](https://docs.everruns.com/explanation/concepts/#why-three-configuration-layers-harness-agent-session). ## Built-in harnesses | Harness | What it provides | Best for | | ----------------------------------------------------------------------------- | ---------------------------------- | -------------------------------------------------- | | [Base](https://docs.everruns.com/built-ins/harnesses/base/) | Empty, no capabilities | Minimal agents, custom tool composition, testing | | [Generic](https://docs.everruns.com/built-ins/harnesses/generic/) | Core capabilities most agents need | General-purpose assistants, coding tasks, research | | [Data Analyst](https://docs.everruns.com/built-ins/harnesses/data-analyst/) | Generic plus SQL, charts, memory | Data workflows | | [Platform Chat](https://docs.everruns.com/built-ins/harnesses/platform-chat/) | Focused platform command surface | Operator chat | The Generic harness is the recommended default. See the [Built-in harnesses reference](https://docs.everruns.com/built-ins/harnesses/base/) for the exact capability bundle each one ships with. ## Naming Every harness has two names: * **`name`**: stable URL-friendly slug (`generic`, `deep-research`). Unique per org. Use this in API calls, CLI, code. * **`display_name`**: human label shown in the UI. `name` format: `[a-z0-9]+(-[a-z0-9]+)*`, max 64 chars, no consecutive hyphens. ## How harnesses combine with agents and sessions The system prompt is built from three layers, each wrapped in XML tags: 1. Harness capabilities (foundation) 2. Agent capabilities (role) 3. Session capabilities (per-conversation extras) ![Capability Hierarchy](https://docs.everruns.com/_astro/capability-hierarchy.DzPrg7Z4_Z11hwqC.svg) The merge is associative: a chain of inherited harnesses produces the same `RuntimeAgent` as a single pre-merged harness. ### The base system prompt is optional A harness bundles more than a prompt, capabilities, MCP servers, a default model, network access, and starter files. Because of that, the base `system_prompt` is **optional**. Omit it (or leave it empty) when a harness exists only to add capabilities or MCP servers on top of a parent: the effective prompt is then composed entirely from the parent harness, the agent, the session, and capability contributions. Empty or whitespace-only prompts contribute nothing, and if no layer contributes a prompt the agent runs with no base system prompt at all. ## Do something * [Customize a harness](https://docs.everruns.com/how-to/customize-a-harness/), build your own as a base for many agents. * [Equip an agent with tools](https://docs.everruns.com/how-to/equip-agents-with-tools/), add capabilities at the agent layer. ## See also * [Built-in harnesses](https://docs.everruns.com/built-ins/harnesses/base/), reference for the shipped harnesses. * [Concepts](https://docs.everruns.com/explanation/concepts/), entity model. --- # Model Context Protocol (MCP) > Everruns is both an MCP server, exposing its agents and tools to external clients with OAuth 2.1, and an MCP client that registers remote servers as virtual capabilities. Source: Everruns speaks the [Model Context Protocol](https://spec.modelcontextprotocol.io) on **both sides**: it exposes its own agents and tools as an MCP server, and it consumes remote MCP servers as agent capabilities. ## Everruns as an MCP server Every Everruns deployment exposes an authenticated MCP endpoint at `/mcp` so external clients, Claude Desktop, Cursor, VS Code, or another agent, can discover and call your agents and tools over JSON-RPC. It is a standard product surface, with no deployment variable or organization feature toggle. * **Transport**: JSON-RPC 2.0 over Streamable HTTP (`POST /mcp`). Protocol versions `2025-06-18` and `2025-03-26` are supported. * **Methods**: `initialize`, `ping`, `tools/list`, `tools/call`, `resources/list`, `resources/read`. * **Auth**: MCP requests authenticate and resolve an organization before dispatch. OAuth 2.1 uses mandatory PKCE, and MCP access tokens are bound to the exact `/mcp` resource so they cannot be reused against the REST API. Unauthenticated requests fail with `401` and protected-resource discovery metadata is served at `/.well-known/oauth-protected-resource/mcp`. * **Entity cards**: under protocol `2025-06-18`, tools like `agent_get_card` return a sandboxed `text/html` MCP App resource at the `ui://` scheme alongside a text summary, so MCP-Apps-aware hosts render rich cards while others fall back to text. Routing is intentionally split: REST under `/api/*`, MCP OAuth under `/oauth/*`, and MCP JSON-RPC at `/mcp`. ## Everruns as an MCP client Register a remote MCP server and its tools appear as a **virtual capability**: auto-discovered, namespaced, and executed alongside built-in capabilities. No code changes are needed to give an agent new tools. * **Org-managed servers**: organization-scoped `McpServer` records connect over remote HTTP (Streamable HTTP). `stdio` is rejected by the hosted control plane and is only available to single-tenant runtime/CLI hosts. * **Scoped `mcpServers`**: harnesses, agents, and sessions can embed remote MCP config directly (the remote-server subset of `.mcp.json`) for session-local or agent-local wiring without creating an org-global record. * **Tool naming**: discovered tools are namespaced per server so they never collide with built-in capabilities. * **Protocol compatibility**: the client negotiates the MCP protocol era per server. By default (`auto`) it issues a session-less `2026-07-28` request and transparently falls back to the stateful `initialize` handshake (`2025-06-18` / `2025-03-26`) for servers that require it, caching the verdict per server. Set the protocol mode to `legacy`, `stable`, or `rc` to pin a specific era and skip negotiation. No setting is needed for the common case. ## When a tool needs a person Some MCP tools cannot finish without a human: a payment to authorize, an API key to paste, a consent screen to click. Under protocol `2026-07-28` the server hands back a URL instead of asking for the value, and Everruns holds the turn until someone answers. See [URL mode elicitation](https://docs.everruns.com/features/mcp-url-elicitation/). ## Use Everruns from your AI tools To connect Claude Code, Codex, or Cursor to a deployment via the `everruns` plugin, see [Use in AI tools](https://docs.everruns.com/getting-started/use-in-ai-tools/). ## Related * [URL mode elicitation](https://docs.everruns.com/features/mcp-url-elicitation/), tool calls that need a person * [Capabilities](https://docs.everruns.com/features/capabilities/), how virtual capabilities fit the capability system * [Slack Integration](https://docs.everruns.com/integrations/slack/), publishing an Agent through a messaging endpoint --- # URL mode elicitation > When an MCP server needs a secret, an authorization, or a payment, Everruns holds the turn and asks a person to finish it in their browser — the value never passes through the client or the model. Source: Some tool calls cannot be completed by an agent alone. A billing server needs the customer to authorize a charge with their bank; an analytics server needs the user’s own API key; a provider needs an OAuth consent screen clicked. The value involved must never reach the agent: not the MCP client, not the model’s context, not the event log. MCP’s answer is **URL mode elicitation** (protocol `2026-07-28`). Instead of asking the client for the value, the server answers `tools/call` with a URL and waits. Everruns supports it on both sides. ## As an MCP client: the turn holds When a tool call comes back with a URL elicitation, Everruns pauses the turn and puts the URL in front of the person, with the domain highlighted: [![](https://docs.everruns.com/videos/mcp-url-elicitation-consent.jpg)](https://docs.everruns.com/videos/mcp-url-elicitation-consent.mp4) The user asks for a charge, the server needs their bank’s authorization, the turn holds on a consent card, and the tool runs once they come back and confirm. Consent is collected in **two steps** — *Open link*, then *I’ve finished — continue* — because only the person knows when the interaction on the other side actually finished. Answering the server the moment the tab opens resumes the turn too early, and the server simply asks again. ### Entering a secret The same flow carries values the agent must never see. Here the server needs the user’s own API key and collects it on its own page: [![](https://docs.everruns.com/videos/mcp-url-elicitation-enter-a-secret.jpg)](https://docs.everruns.com/videos/mcp-url-elicitation-enter-a-secret.mp4) The key goes from the user’s browser straight to the provider. The Everruns transcript carries the report, never the key. ### What the client guarantees * **The capability is declared only when a human can answer.** A host with no way to reach a person declares no `elicitation` capability at all, so a compliant server cannot ask. * **The URL is validated before anyone sees it**: `https` only (loopback `http` for local development), so a consent surface is never handed a `javascript:` or `file:` URL. The client never fetches it. * **The domain is shown, and Punycode is flagged.** Internationalized domains are legitimate but can impersonate; the card says so. * **Consent is single use and bound to one domain.** A server that elicits `pay.example.com`, waits for the click, then elicits somewhere else on the retry gets no reuse of that consent — the user is asked again. * **A refusal is final.** Declining ends the call and tells the agent to continue without the tool. ### Refusing [![](https://docs.everruns.com/videos/mcp-url-elicitation-decline.jpg)](https://docs.everruns.com/videos/mcp-url-elicitation-decline.mp4) The user declines, and the agent carries on without the tool instead of asking again. ### One consent, one domain [![](https://docs.everruns.com/videos/mcp-url-elicitation-domain-swap.jpg)](https://docs.everruns.com/videos/mcp-url-elicitation-domain-swap.mp4) Consent was given for one host. The server elicits a different one on the retry, so the consent is not reused: the user is asked afresh, for the new domain. ## As an MCP server: Everruns serves the form Everruns’ own `/mcp` endpoint uses the same mechanism when a client asks it to store a secret or connect a provider. `session_set_secret` never accepts a value as a parameter: it answers with a URL to a form Everruns serves, the user types the value there, and the retry confirms it is stored. The MCP client that started the call only ever holds the URL. The page requires the visitor’s own session on top of the signed link, and refuses anyone but the user the elicitation was minted for — the link alone grants nothing, which is what closes the phishing case the spec warns about. [![](https://docs.everruns.com/videos/mcp-url-elicitation-as-server.jpg)](https://docs.everruns.com/videos/mcp-url-elicitation-as-server.mp4) An MCP client asks Everruns to store a secret, gets a URL back, the user fills in the form Everruns serves, and the retry confirms it is stored. ## Clients that cannot render a card Pausing is a client capability, declared per session: ```json { "hints": { "url_elicitation": true } } ``` The Chat UI declares it automatically. A client that does not gets the older behaviour: the turn continues and the elicitation reaches the user through the tool result, as an actionable `url_elicitation_required` payload with the URL and the server’s reason. To complete such a call from your own client, see [Complete a URL elicitation over the API](https://docs.everruns.com/how-to/complete-a-url-elicitation/). ## Protocol support URL mode elicitation is `2026-07-28` only. In earlier eras elicitation is a server-initiated request over a server-to-client stream this transport does not open, so Everruns declares nothing regardless of what the host can do. ## Try it `examples/mcp-url-elicitation/` in the repository has a dependency-free MCP server that elicits, and a script that drives the whole flow over the API. ## Related * [MCP](https://docs.everruns.com/features/mcp/), Everruns on both sides of the protocol * [Capabilities](https://docs.everruns.com/features/capabilities/), how MCP servers become agent tools --- # Agent and User Memory > Understand organization, agent, and user memory scopes, their automatic mount paths, and the privacy and access rules for each. Source: Memory keeps files available across sessions. Everruns provides three ownership scopes so shared organization knowledge, an agent’s learned context, and a user’s preferences do not have to share the same access boundary. ## The three scopes | Scope | Lifetime and owner | How it enters a session | Access | | ------------ | --------------------------------------------- | ----------------------------------------------------------------------------------------------- | -------------------------------------------------------------- | | Organization | A named store managed within one organization | Select it in the `memory` capability and choose a path under `/workspace` | Read-only by default; read-write must be selected explicitly | | Agent | One server-managed store per agent | Automatically mounted for sessions hosted by that agent at `/memory/agent` | Read-write in the hosted session | | User | One server-managed store per user | Automatically mounted in the owning user’s private, default session workspace at `/memory/user` | Read-write for the owner and the agent working in that session | Organization memories are appropriate for shared references such as runbooks or product documentation. Agent memory follows one host agent across its sessions. User memory follows one user so preferences and personal context can persist across their sessions. ## Privacy defaults **User memory is private by default.** Only the session owner may access `/memory/user` through user-facing session file APIs. Other users cannot read or mutate the subtree, and file searches redact matches from it. Internal runtime access lets the agent working for the owner read and update that memory. User memory is not mounted into caller-attached shared workspaces. Everruns waits to expose it there until mounts can be participant-local instead of visible to the entire workspace. Agent memory is separate from user memory. It is shared by sessions hosted by the same agent, so do not use `/memory/agent` for user-private data. A guest agent’s private memory is not merged into a shared session’s workspace-wide `/memory/agent` path. ## How automatic mounts work When a session starts, Everruns lazily creates any missing scoped stores and mounts their current files: * `/memory/agent` contains the host agent’s persistent files. * `/memory/user` contains the session owner’s persistent files when the session uses the owner’s private default workspace. Both automatic mounts are read-write. The regular file tools and Workspace UI traverse them alongside session files, and writes persist to the scoped memory for later sessions. The `/memory/*` namespace is reserved. You cannot use it for caller-supplied initial files or for mounts configured through the public `memory` capability. ## Organization memory access Organization memories are created and managed through the Memory UI and `/v1/memories` API. Add the `memory` capability to select an active organization memory, its mount path, and its access mode. * Omitted access mode defaults to `readonly`. * A `readwrite` mount writes through to the durable organization memory. * Source-backed GitHub or Git memories are always read-only. * Agent- and user-scoped memories are server-managed and cannot be selected through `memory.mounts`. See [Memory model](https://docs.everruns.com/advanced/memory-model/) for the relationship between durable Memory and a session Workspace, or the [API reference](https://docs.everruns.com/api/) for current organization-memory schemas. ## See also * [Memory model](https://docs.everruns.com/advanced/memory-model/), Workspace and durable Memory architecture. * [Session participants](https://docs.everruns.com/features/session-participants/), host and guest agent behavior in shared sessions. * [File System capability](https://docs.everruns.com/capabilities/file-system/), tools that access session and mounted files. --- # SDKs > Official client libraries for Rust, Python, and TypeScript — typed clients, async APIs, SSE streaming with automatic reconnection. Source: The Everruns SDKs are official client libraries for building agent applications. Rust, Python, and TypeScript with a consistent API across all three. What the SDKs handle for you: * **Consistent API** across languages * **Async/await patterns** throughout * **SSE streaming** with automatic reconnection, heartbeat-based stale detection, and `since_id` resumption * **Typed models** generated from the OpenAPI spec * **Sub-client organization** (`agents`, `sessions`, `messages`, `events`, `filesystem`, …) For a hands-on lesson, see [Build your first agent](https://docs.everruns.com/tutorials/building-agents-using-sdk/) or the minimal [Run an Agent](https://docs.everruns.com/tutorials/run-an-agent/) notebook. ## Install * Rust Requires Rust 1.70+ ```bash cargo add everruns-sdk ``` * Python Requires Python 3.10+ ```bash pip install everruns-sdk ``` * TypeScript Requires Node.js 18+ ```bash npm install @everruns/sdk ``` ## Authenticate All SDKs read `EVERRUNS_API_KEY` from the environment by default. You can also pass it explicitly. * Rust ```rust use everruns_sdk::Client; let client = Client::from_env()?; // from env let client = Client::new("your-api-key"); // explicit ``` * Python ```python from everruns_sdk import Client client = Client() # from env client = Client(api_key="your-api-key") # explicit ``` * TypeScript ```typescript import { Client } from "@everruns/sdk"; const client = new Client(); // from env const client = new Client({ apiKey: "your-api-key" }); // explicit ``` ## API coverage | Resource | Operations | | --------------------- | ------------------------------------------------------------------- | | **Agents** | Create, list, get, update, upsert, archive, import, export, preview | | **Sessions** | Create, list, get, update, delete, cancel | | **Messages** | Create, list | | **Events** | Poll, stream (SSE) | | **Capabilities** | List, get | | **LLM Providers** | Create, list, get, update, delete, sync models | | **LLM Models** | Create, list, get, update, delete | | **MCP Servers** | Create, list, get, update, delete | | **Filesystem** | List, read, create, update, delete, move, copy, grep, stat | | **Session Databases** | Create, list, get, delete, schema | | **Images** | Upload, list, get, thumbnail, delete | | **Organizations** | Create, list, get, update | | **Scheduled Tasks** | Create, list, get, update, delete, pause, resume, trigger | ## Error handling | Error type | Description | | --------------------- | -------------------------- | | `AuthenticationError` | Invalid or missing API key | | `NotFoundError` | Resource not found | | `RateLimitError` | Rate limit exceeded | | `ApiError` | General API error | * Rust ```rust use everruns_sdk::Error; match client.agents().get("invalid-id").await { Ok(agent) => println!("Found: {}", agent.name), Err(Error::NotFound(msg)) => println!("Not found: {}", msg), Err(Error::Authentication(msg)) => println!("Auth error: {}", msg), Err(e) => println!("Other error: {}", e), } ``` * Python ```python from everruns_sdk import NotFoundError, AuthenticationError try: agent = await client.agents.get("invalid-id") except NotFoundError as e: print(f"Not found: {e}") except AuthenticationError as e: print(f"Auth error: {e}") ``` * TypeScript ```typescript import { NotFoundError, AuthenticationError } from "@everruns/sdk"; try { const agent = await client.agents.get("invalid-id"); } catch (e) { if (e instanceof NotFoundError) { console.log(`Not found: ${e.message}`); } else if (e instanceof AuthenticationError) { console.log(`Auth error: ${e.message}`); } } ``` ## Do something * [Build your first agent](https://docs.everruns.com/tutorials/building-agents-using-sdk/) — guided tutorial. * [Stream events with the SDK](https://docs.everruns.com/how-to/stream-events/) — common streaming patterns. * [Handle errors and cancel turns](https://docs.everruns.com/how-to/handle-errors-and-cancellation/) — graceful failure paths. * [Orchestrate multi-agent pipelines](https://docs.everruns.com/how-to/orchestrate-multi-agent-pipelines/) — chain agents together. ## See also * [API reference](https://docs.everruns.com/api/) — every endpoint, generated from OpenAPI. * [Event Reference](https://docs.everruns.com/event-reference/) — every event type. * [GitHub Repository](https://github.com/everruns/sdk) — source code and examples. ## Overview video [Everruns SDK Overview](https://www.youtube.com/embed/1FfGKUTzBzA) --- # Session Participants > Invite agents into a shared session, address a specific agent for a turn, and understand host, member, user, join, and leave behavior. Source: A session can include more than one agent and more than one user. Session participants record who is present, whether they are the host or a member, and when they joined or left. ## Host and member roles An agent-backed session has one active host agent. The host supplies the session’s harness and answers user turns by default. Other agents and users join as members: * an **agent member** can be addressed for an individual turn; * a **user member** records a person participating in the session, but cannot be addressed as an agent responder; and * a member that leaves remains in participant history with a leave time. Inviting a member agent does not replace the host or the host’s harness. The invited agent contributes its behavior, model defaults, capabilities, and client tools only when a turn is addressed to it. ## Invite an agent in the UI The session view shows multi-party membership in the **In this session** rail on desktop. It labels each participant as **Host** or **Member** and as **Agent** or **User**. To add an agent: 1. Open **In this session**. 2. Select **Invite agent**. 3. Choose an agent that is not already active in the session. The agent joins as a member. The rail also shows participants who have left. Use the remove action on an active member to make it leave; the host cannot leave through the ordinary participant action. If a user who left sends another message, that user rejoins automatically with a new participation interval. Agents can perform the same operation with invite-mode handoff. An agent with the `agent_handoff` capability calls `spawn_agent` with `mode = invite`. Unlike foreground or background handoff, invite mode joins the target agent to the current session instead of creating a child session. ## Address an agent for one turn When at least one active member agent is available, the composer shows an **Address** selector: * **Session host (default)** sends the turn to the host agent. * Selecting a member agent sends that turn to the selected participant. Addressing is per turn. It does not change the session’s host or default responder. A participant must still be active and must be an agent; requests that address a user or a participant who already left are rejected. ## API Participant membership is managed below a session: | Method | Path | Purpose | | -------- | --------------------------------------------------------- | ----------------------------------------------- | | `GET` | `/v1/sessions/{session_id}/participants` | List active and past participants in join order | | `POST` | `/v1/sessions/{session_id}/participants` | Add an agent or user member | | `DELETE` | `/v1/sessions/{session_id}/participants/{participant_id}` | Mark a member as having left | To address an agent, set `addressed_participant_id` when creating a message with `POST /v1/sessions/{session_id}/messages`. Omit it to use the host. The participant list is the source of truth for join and leave history. Join and leave do not emit dedicated participant events on the session SSE stream. See the [API reference](https://docs.everruns.com/api/) for current schemas and authorization requirements. ## See also * [Agent triggers](https://docs.everruns.com/features/agent-triggers/), proactive runs start sessions with the trigger’s agent as host. * [Sub Agents capability](https://docs.everruns.com/capabilities/sub-agents/), foreground, background, and invite handoff modes. * [Core concepts](https://docs.everruns.com/explanation/concepts/), sessions, turns, and agents. --- # Agent Skills > Portable instruction packages following the agentskills.io open spec — progressive disclosure, bundled scripts, on-demand activation. Source: **Agent Skills** are portable instruction packages following the [Agent Skills](https://agentskills.io/) open specification. They keep the agent’s context efficient through *progressive disclosure*: the agent sees only short names and descriptions until it activates a skill, at which point the full instructions and bundled resources load. ## Overview video [Agent Skills Overview](https://www.youtube.com/embed/mNqXP4NA_8U) ## Three-stage disclosure 1. **Discovery** (\~100 tokens per skill) — names and descriptions appear in the system prompt under ``. 2. **Activation** (under 5,000 tokens) — full SKILL.md instructions load when the agent calls `activate_skill`. 3. **Resources** — bundled files mount at `/skills/{name}/` and are read with the normal filesystem tools. This keeps thousands of skills available to an agent without burning context on the ones it doesn’t need. ## Two ways to use skills | Source | Where they live | When to use | | ---------------- | ------------------------------------------------------------------------------------------------ | ---------------------------------------------------- | | Workspace skills | `/.agents/skills/` in the session VFS | Project-specific skills; per-session experimentation | | Registry skills | Organization-wide via the [Skills Registry](https://docs.everruns.com/features/skills-registry/) | Shared across agents; managed via API | The built-in `skills` capability handles workspace discovery. Registry skills appear in the capability system as virtual capabilities (`skill:{uuid}`). ## Do something * [Package an agent skill](https://docs.everruns.com/how-to/package-a-skill/) — author a SKILL.md, bundle scripts. * [Publish a skill to the registry](https://docs.everruns.com/how-to/publish-a-skill-to-the-registry/) — share it. ## See also * [Agent Skills capability reference](https://docs.everruns.com/capabilities/agent-skills/) — tools, dependencies, config. * [Skills Registry](https://docs.everruns.com/features/skills-registry/) — the org-wide registry. * [SKILL.md format spec](https://agentskills.io/) — upstream open spec. --- # Skills Registry > API endpoints for managing organization-wide skill packages, create from SKILL.md or ZIP, validate, assign to agents as virtual capabilities. Source: The **Skills Registry** stores skills at the organization level. Registry skills persist across sessions and appear in the capability system as virtual capabilities with ID `skill:{uuid}`. They can be assigned to any agent like any other capability. For workspace-scoped skills (drop a SKILL.md into a session’s `/.agents/skills/`), see [Agent Skills](https://docs.everruns.com/features/skills/). ## API surface | Method | Path | Description | | ------ | ------------------------- | ------------------------- | | POST | `/v1/skills` | Create from SKILL.md | | POST | `/v1/skills/upload` | Create from ZIP archive | | GET | `/v1/skills` | List | | GET | `/v1/skills/{id}` | Get metadata | | GET | `/v1/skills/{id}/content` | Get full content | | PATCH | `/v1/skills/{id}` | Update | | DELETE | `/v1/skills/{id}` | Delete | | POST | `/v1/skills/validate` | Validate without creating | ## ID formats | Source | ID | Example | | --------- | ------------------------------------ | -------------------------------------------- | | Registry | `skill:{uuid}` | `skill:550e8400-e29b-41d4-a716-446655440000` | | Workspace | Aggregated under `skills` capability | , | ## Dependencies Registry skills automatically depend on `session_file_system` so bundled resources can be read after activation. You don’t need to add it explicitly. ## Security * Archive uploads are validated against path traversal, ZIP bombs, and size limits. * Skill instructions are returned as tool results, not injected into the system prompt, they cannot bypass capability isolation. * Skill names are unique per organization. * Disabled skills are hidden from listings. ## Do something * [Publish a skill to the registry](https://docs.everruns.com/how-to/publish-a-skill-to-the-registry/), full upload, validate, assign flow. * [Package an agent skill](https://docs.everruns.com/how-to/package-a-skill/), author the SKILL.md. ## See also * [Agent Skills](https://docs.everruns.com/features/skills/), the concept and workspace flow. * [API reference](https://docs.everruns.com/api/), full request/response schemas. --- # Management UI > Manage agents, sessions, capabilities, settings, files, and event streams through the optional web interface. Source: While Everruns is a headless agent platform designed for API-first integration, it provides an optional management UI for administrative tasks and session monitoring. ## Overview The management UI is a Next.js application that provides: * Agent management (create, edit, delete) * Session monitoring and chat interface * Capabilities browser * Settings management (LLM providers, personal access tokens, team members) * Dashboard with system statistics Access the UI at `http://localhost:9300` when running locally. ## Navigation The sidebar provides access to main sections: | Section | Description | | ------------ | ------------------------------------------------------------- | | Dashboard | Overview statistics and quick actions | | Agents | List, create, and manage agents | | Capabilities | Browse available capabilities | | Settings | Configure providers, personal access tokens, and team members | ## Dashboard The dashboard provides an at-a-glance view of your system: * **Stats Cards**: Total agents, active sessions, and other metrics * **Recent Agents**: Quick access to recently created or updated agents * **Quick Actions**: Shortcuts to create agents or browse the agent list ## Agents ### Agent List The agents page displays all agents in a card grid layout. ![Agents page showing card grid layout](https://docs.everruns.com/_astro/ui.D3k5dyu-_3hjoA.webp) Each card shows: * Agent name and status badge (active/inactive) * Truncated ID * Description preview * Enabled capabilities with icons * Tags * Creation date * Edit button Click a card to view the agent details, or click the edit icon to modify the agent. ### Agent Detail The agent detail page shows: * **System Prompt**: Full system prompt with markdown rendering * **Sessions List**: All sessions for this agent with status indicators * **Capabilities**: Enabled capabilities with descriptions * **Configuration**: Default model, description, tags, timestamps Actions available: * **Edit**: Modify agent configuration * **New Session**: Create a new conversation session ### Create/Edit Agent The agent form allows you to configure: * **Name**: Display name for the agent * **Description**: Optional description * **System Prompt**: Instructions for the agent (supports markdown) * **Default Model**: LLM model to use for conversations * **Capabilities**: Enable/disable available capabilities * **Tags**: Organizational tags ## Sessions ### Session View Each session has three tabs: #### Chat Tab The primary interface for viewing and participating in conversations: * Message history with user messages (dark bubbles) and agent responses * Tool call visualization with expandable details * Tool results displayed inline * Message input with keyboard shortcuts (Enter to send, Shift+Enter for newline) * Reasoning effort selector (for models that support extended thinking: Anthropic Claude, OpenAI GPT-5.x, o-series) #### File System Tab Browse and manage files associated with the session’s sandboxed environment. #### Events Tab View raw session events for debugging: * Sequence number * Event type (input.message, output.message.completed, tool.completed, etc.) * Timestamp * JSON data payload ### Session Status Sessions display their current status: | Status | Badge | Description | | ------- | --------- | ------------------------------ | | started | Outline | Newly created, no messages yet | | idle | Secondary | Ready for input | | active | Primary | Currently processing | ## Capabilities The capabilities page lists all available functionality modules: * **Summary Panel**: Counts by status (available, coming soon, deprecated) * **Category Tags**: Filter by capability type * **Capability Cards**: Click to view details including tools and configuration Each capability card shows: * Icon and name * Identifier (for API use) * Status badge * Description * Category tag ## Settings ### LLM Providers Configure language model providers: * Add provider credentials (API keys) * Enable/disable specific models * Set default models for agents ### Personal access tokens Manage personal access tokens for programmatic access. Tokens are tied to your user account (not an organization) and inherit access to every organization available to your account: * Create new personal access tokens * View existing tokens (values hidden) * Revoke tokens ### Members View and manage team members (when authentication is enabled). --- # Architecture > The Everruns system architecture: control plane, worker nodes, durable execution engine, and SSE event streaming. Source: Everruns is a **headless durable agentic harness engine** built for reliability and scale. It provides a REST API for managing agents, sessions, and runs with real-time event streaming via SSE. ## Platform Overview ![Platform Overview](https://docs.everruns.com/_astro/platform-overview.G0xqOkAk_24MdNC.svg) ## Key Design Principles | Principle | Description | | ------------------------ | --------------------------------------------------------- | | **Headless / API-First** | Integrate via REST API. No UI required for production. | | **Agentic Loop** | Core pattern: Reason → Act, repeated until task complete. | | **Durable Execution** | Agent state survives restarts. Never lose progress. | | **Horizontal Scaling** | Add workers to increase throughput. | | **Provider Agnostic** | OpenAI, Anthropic, Gemini, or custom LLM providers. | ## Components For the deployable shape of these components, which run as separate processes, which are required, and which are optional infrastructure like NATS and Valkey, see [Physical Architecture](https://docs.everruns.com/advanced/physical-architecture/). ### Control Plane Central coordinator that exposes the REST API and manages all state in PostgreSQL: * **Agents** - AI assistant configurations * **Sessions** - Conversation state and history * **Events** - Real-time event streaming via SSE ### Workers Stateless executors that run agentic loops composed from atoms (Input → Reason → Act). Workers are: * **Scalable** - Add more to handle concurrent sessions * **Fault-tolerant** - Failed tasks automatically recovered * **Stateless** - All state lives in PostgreSQL ### Management UI (Optional) Administrative interface for platform operators. **Not required for production use.** * Agent configuration * Session monitoring * LLM provider settings See [Management UI](https://docs.everruns.com/features/ui/) for details. ## Further Reading * [Physical Architecture](https://docs.everruns.com/advanced/physical-architecture/) - The deployable components: PostgreSQL, NATS, Valkey, workers, and how they connect * [Introduction](https://docs.everruns.com/getting-started/introduction/) - Getting started * [API Reference](https://docs.everruns.com/api/) - Full API documentation * [Capabilities](https://docs.everruns.com/features/capabilities/) - Extend agent functionality --- # Concepts > How harnesses, agents, endpoints, sessions, turns, events, capabilities, tools, and files fit together in the execution model. Source: This page is the **concept cheat-sheet**: short definitions of every entity, organised into three layers (high-level execution model, session internals, and settings). For the design rationale behind each entity, read [Core concepts](https://docs.everruns.com/explanation/concepts/) under Explanation. ## High Level Harness and Agent are **configuration containers**: they hold capabilities and define behavior. At runtime, their configuration merges into a **RuntimeAgent** which executes inside a Session. ![Configuration Hierarchy](https://docs.everruns.com/_astro/configuration-hierarchy.C1WesMao_1YIQ9o.svg) * **Solid arrows**: configuration ownership: Harness has Agents and Capabilities, Agent has Capabilities * **Dashed arrows**: runtime assembly: config merges into RuntimeAgent, which executes in a Session ### Harness A Harness is what an agent runs on. It defines the execution environment, defaults, and constraints for sessions: which capabilities are available by default, the default model, network access, and starter files. * There can be many harnesses in the system * Each agent holds exactly one harness reference * Each session runs on exactly one harness, the agent’s unless the session names another * A harness can have capabilities attached to it A Harness is not the agent loop. “Agent harness” commonly means that loop elsewhere, and Everruns uses the word that way when describing itself as a durable agentic harness engine. The loop is the runtime; a Harness is configuration the runtime reads. See [Harnesses](https://docs.everruns.com/features/harnesses/). ### Agent An Agent is a domain-specific or task-specific configuration for the agentic loop. It defines the system prompt, the default LLM model, and which capabilities are enabled. * There can be many agents in the system * A session may or may not have an agent assigned * Agents can be assigned or changed during the lifetime of a session * Each agent has capabilities with position ordering * Each agent references a default LLM model ### Session A Session is a working instance of an agentic loop. It is configured by its harness and, optionally, by an agent. Sessions are the primary execution context where conversations happen. * There can be many sessions in the system * Each session has an assigned harness * The agent is optional and can change over the session’s lifetime * Sessions can have their own capabilities, which are additive to the agent’s capabilities * Sessions can override the LLM model * Status flow: `started` → `active` → `idle` (sessions work indefinitely) ### Capability A Capability is a modular, reusable configuration unit that extends the behavior of a harness, agent, or session. Each capability can contribute: 1. **System prompt additions**: text prepended to the agent’s prompt 2. **Tools**: functions the agent can invoke 3. **Mount points**: files and directories populated in the session filesystem * Can be attached to a harness, an agent, or a session * Session capabilities are additive to agent capabilities * Built-in capabilities use `snake_case` IDs (e.g., `current_time`, `web_fetch`) * MCP servers appear as virtual capabilities with `mcp:{uuid}` IDs * Capabilities can depend on other capabilities, resolved in topological order See [Capabilities](https://docs.everruns.com/features/capabilities/) for a full list and configuration details. ### Tool A Tool is a function the agent can invoke during execution. Tools are provided by capabilities. * Built-in tools have no name prefix * MCP tools are prefixed: `mcp_{server_name}__{tool_name}` * Executed during the act phase of a turn ### Endpoint An Endpoint is an Agent-owned way for an external caller to reach that Agent. Slack, AG-UI, A2A, FCP, and Public Chat each use an endpoint with transport-specific configuration. * Each endpoint belongs to exactly one Agent. * Each endpoint has its own publish state, credentials, identity, and version policy. * Lifecycle: `draft` → `live` → `draft`. * Incoming messages route to sessions by the endpoint’s session strategy. * An Agent can own multiple independently published endpoints. Open an Agent’s **Integrations** tab to create and manage endpoints. See [Slack Integration](https://docs.everruns.com/integrations/slack/) for a complete example. *** ## Session Internals Each session contains turns, messages, events, an isolated filesystem, and key-value storage. ![Session Internals](https://docs.everruns.com/_astro/session-internals.GFlKvg-t_1OflDF.svg) ### Turn A Turn is one iteration of the agent loop: reason (call the LLM) then act (execute tools). * Each turn belongs to a session * A turn produces messages and emits events * Lifecycle: `turn.started` → reason → act → `turn.completed` (or `turn.failed`) #### The Agentic Loop Understanding the reason-act loop is key to building effective agents. Here’s what happens inside each turn: ![Agentic Loop](https://docs.everruns.com/_astro/agentic-loop.DtZaK05U_1OflDF.svg) Each iteration: 1. **Reason**: The LLM receives the full conversation history (system prompt + messages + tool results) and produces either a text response or tool calls 2. **Act**: All tool calls from the LLM are executed in parallel. Results are added to the conversation history 3. **Loop**: If there were tool calls, go back to Reason. If the LLM produced a final text response, the turn is complete The loop runs for a maximum of **10 iterations** per turn to prevent runaway execution. #### Durable Execution In production mode (PostgreSQL-backed), each step is a separate durable task: ![Durable Execution Pipeline](https://docs.everruns.com/_astro/durable-execution-pipeline.B2_Vssr2_17VArw.svg) If a worker crashes mid-turn, the control plane detects the missed heartbeat and re-queues the task for another worker. Your application sees a brief delay, not a failure. ### Message A Message is a conversation entry reconstructed from the event log. Messages are not stored in a separate table. * Roles: `user`, `agent`, `tool_result` * Content is an array of parts: text, image, tool\_call, tool\_result * Agent messages may include extended thinking content from reasoning models (Anthropic Claude, OpenAI GPT-5.x and o-series) * Supports per-message controls such as model override and reasoning effort ### Event An Event is an immutable, append-only record. Events are the primary data store for conversations and SSE notifications. * Atomic per-session sequence numbering * Types: input, output, turn, atom, tool, LLM, session lifecycle * Cannot be updated or deleted * Carries correlation context: turn ID, input message ID, execution ID See [Events](https://docs.everruns.com/features/events/) for the full event reference. ### File System Each session has an isolated virtual filesystem stored in PostgreSQL. * Paths are relative to `/workspace` * Capabilities can mount initial files and directories * Shared between the FileSystem and BashkitShell capabilities * Files support an optional read-only flag ### Key-Value Store Each session has scoped storage with two tiers: * **Key/Value**: plain text storage for general data such as state, preferences, or intermediate results * **Secrets**: AES-256-GCM encrypted at rest for API keys, tokens, and credentials * Storage is session-isolated and cannot be accessed across sessions *** ## Settings System-wide configuration for LLM providers, models, and MCP servers. ![Settings](https://docs.everruns.com/_astro/settings.D_FjEE2q_Z28BEir.svg) ### LLM Provider An LLM Provider is a configured API provider such as OpenAI or Anthropic. Providers store encrypted API keys and contain models. * Provider types include `openai`, `openrouter`, `openai_completions`, `anthropic`, `gemini`, and `bedrock` * Each provider contains many models * Default providers (OpenAI, Anthropic) are seeded on startup ### LLM Model An LLM Model is a specific model within a provider (e.g., `gpt-5.2`, `claude-sonnet-5`). * Each model belongs to one provider * Sources: predefined, discovered from the provider API, or manually added * Model resolution priority: message controls → session override → agent default → system default ### MCP Server An MCP Server is a remote server that exposes tools via the Model Context Protocol. MCP servers are integrated as virtual capabilities. * Each server becomes a capability with ID `mcp:{server_uuid}` * Tools are discovered at runtime and cached with a 24-hour TTL * Tool names are prefixed to avoid conflicts: `mcp_{server}__{tool}` * Execution happens via HTTP JSON-RPC --- # Docker Compose > Deploy the Everruns platform with Docker Compose: control plane, workers, UI, and PostgreSQL. Source: Deploy the complete Everruns platform using Docker Compose. This guide sets up the control plane, workers, UI, and database in a single command. ## Prerequisites * Docker Engine 20.10+ * Docker Compose v2.0+ * 4GB available RAM ## Quick Start ### 1. Download Docker Compose File ```bash # Create directory and download docker-compose file mkdir everruns && cd everruns curl -o docker-compose.yaml https://raw.githubusercontent.com/everruns/everruns/main/examples/docker-compose-full.yaml ``` ### 2. Generate Encryption Key Everruns encrypts LLM API keys at rest. Generate a key: ```bash python3 -c "import os, base64; print('kek-v1:' + base64.b64encode(os.urandom(32)).decode())" ``` ### 3. Create Environment File Create a `.env` file with your encryption key and optional LLM API keys: .env ```bash SECRETS_ENCRYPTION_KEY=kek-v1: # Optional: Add API keys here to skip UI configuration DEFAULT_OPENAI_API_KEY=sk-... DEFAULT_ANTHROPIC_API_KEY=sk-ant-... DEFAULT_GEMINI_API_KEY=AIza... ``` ### 4. Start Services ```bash docker compose pull # Fetch latest images docker compose up -d ``` The published compose file defaults to app entry point on `9300`. If that port is busy, override before startup: ```bash EXAMPLE_PROXY_PORT=10300 docker compose up -d ``` This starts: * PostgreSQL database * Control plane API * 3 worker instances * Next.js UI * Caddy reverse proxy ### 5. Access the Platform | Service | URL | | ------------------ | -------------------------------------------------------------- | | **Web UI** | | | **API** | … | | **OAuth** | … | | **MCP** | | | **OAuth Metadata** | | | **Health Check** | | ## Configuration ### Run Multiple Copies If you want multiple Everruns compose stacks on the same machine, set both a Compose project name and host-port overrides: ```bash COMPOSE_PROJECT_NAME=everruns-demo-2 \ EXAMPLE_PROXY_PORT=10300 \ docker compose up -d ``` ### Configure LLM Provider If you didn’t set LLM API keys (`DEFAULT_OPENAI_API_KEY`, `DEFAULT_ANTHROPIC_API_KEY`, or `DEFAULT_GEMINI_API_KEY`) in your `.env` file, configure via UI: 1. Open 2. Navigate to **Settings** > **Providers** 3. Add your OpenAI or Anthropic API key 4. Save and verify connection ### Create Your First Agent 1. Go to **Agents** in the UI 2. Click **Create Agent** 3. Set a name and system prompt 4. Select your configured LLM provider 5. Save the agent ### Start a Session ```bash # Create a session (agent_id in request body) curl -X POST http://localhost:9300/api/v1/sessions \ -H "Content-Type: application/json" \ -d '{"agent_id": "{agent_id}"}' # Send a message curl -X POST http://localhost:9300/api/v1/sessions/{session_id}/messages \ -H "Content-Type: application/json" \ -d '{"message": {"role": "user", "content": [{"type": "text", "text": "Hello!"}]}}' ``` ## Scaling Workers Add more workers by scaling the worker services: ```bash # Scale to 5 workers docker compose up -d --scale worker-1=1 --scale worker-2=1 --scale worker-3=3 ``` Or modify `docker-compose.yaml` to add more worker services. ## Monitoring ### View Logs ```bash # All services docker compose logs -f # Specific service docker compose logs -f server docker compose logs -f worker-1 ``` ### Distributed Tracing Set `OTEL_EXPORTER_OTLP_ENDPOINT` to export traces to any OTLP-compatible backend (Grafana Tempo, Datadog, etc.). ## Stopping Services ```bash # Stop all services docker compose down # Stop and remove volumes (deletes data) docker compose down -v ``` ## Troubleshooting ### Database Connection Issues If services fail to connect to PostgreSQL: ```bash # Check postgres health docker compose ps postgres # View postgres logs docker compose logs postgres ``` ### Migration Failures Migrations are auto-applied when the API server starts. If migrations fail: ```bash # Check API logs for migration errors docker compose logs api # Restart API to retry migrations docker compose restart api ``` To check migration status before deployment: ```bash docker compose exec api everruns-admin migrate-info ``` ### Worker Not Processing Verify workers can reach the control plane: ```bash # Check worker logs docker compose logs worker-1 # Verify gRPC connection docker compose exec worker-1 /bin/sh -c "echo" || echo "Cannot exec (distroless image)" ``` ## Next Steps * [API Reference](https://docs.everruns.com/api/) - Full API documentation * [Capabilities](https://docs.everruns.com/features/capabilities/) - Extend agent functionality * [Environment Variables](https://docs.everruns.com/sre/environment-variables/) - Advanced configuration --- # Introduction > What Everruns is, what it provides, and where to go next. Source: Everruns is a durable agentic harness engine built on Rust. It provides APIs for managing agents, sessions, and runs, streams events over SSE, and persists execution state in PostgreSQL so a long-running task survives a worker restart. ## Key Concepts ### Agents An agent is a configuration the runtime executes. Each one carries: * A system prompt that defines its behavior * A set of capabilities that provide tools * Model configuration for the underlying LLM ### Sessions Sessions represent conversations with an agent. Each session maintains: * Conversation history * Current execution state * Configuration overrides ### Capabilities A capability is a unit of agent behavior. Each one can: * Add instructions to the system prompt * Provide tools for the agent to use * Modify execution behavior See [Capabilities](https://docs.everruns.com/features/capabilities/) for more details. ## Getting Started ### Ways to run Everruns * **[Everruns Cloud](https://app.everruns.com)**: the hosted Platform, open in early access. We run the server, database, and workers. Free for now, and you bring your own model provider keys. * **[Docker Compose](https://docs.everruns.com/getting-started/docker-compose/)**: run the full Platform on infrastructure you control. * **[Framework](https://docs.everruns.com/framework/)**: embed durable agents in a Rust process, with no separate Platform to operate. ### Quick Start 1. Deploy Everruns using the provided Docker images, or create an account on [Everruns Cloud](https://app.everruns.com) and skip this step 2. Configure your LLM providers via the Settings UI 3. Create an agent 4. Start sessions and interact through the API or UI ### API Access The API is available at your deployment URL: * **API Base**: `https://your-domain.com/api/v1/` * **OpenAPI Spec**: `https://your-domain.com/api-doc/openapi.json` ## Architecture Everruns uses a layered architecture: * **API Layer**: HTTP endpoints (axum), SSE streaming * **Core Layer**: Agent abstractions, capabilities, tools * **Worker Layer**: Durable workflows for reliable execution * **Storage Layer**: PostgreSQL with encrypted secrets and durable execution state See [Architecture](https://docs.everruns.com/getting-started/architecture/) for how these layers interact. --- # Use in AI Tools > Set up Everruns in AI tools through the Everruns plugin. Source: # Use in AI Tools (Everruns Plugin) The `everruns` plugin connects Claude Code, Codex, and Cursor to any Everruns deployment over MCP. It ships skills, slash commands, and agents; Codex setup additionally uses the plugin’s `defaultPrompt` and `description`. ## Quickstart (local Everruns) ```bash just up just agent-auth PROVIDER=cursor # or vscode, claude, codex, gemini, droid, opencode ``` This scaffolds a plugin that talks to your local deployment. Point the plugin at a different deployment by setting `EVERUNS_MCP_URL` (defaults to `https://app.everruns.com/mcp`). ## Codex (ChatGPT + CLI) Use the plugin’s `defaultPrompt` and `description` so you do not have to type OAuth scopes and MCP labels by hand: ```jsonc { "title": "Everruns", "text": "...", "images": ["docs/getting-started/codex-everruns-plugin.png"], "skill": "everruns", "commands": ["commands"], "mcp": "everruns", "defaultPrompt": "You are using Everruns at ${EVERUNS_MCP_URL:-https://app.everruns.com/mcp}. Use the everruns skill...", "description": "Connects Codex to Everruns over MCP with skills, slash commands, and agents." } ``` ![Everruns Codex plugin](https://docs.everruns.com/_astro/codex-everruns-plugin.BnrxNxgM_Zhjtkg.webp) To install the published plugin, open the `everruns` plugin page in Codex and choose **Add to Codex**. ## Plugin layout The portable plugin lives in `plugins/everruns/`: * `plugin.json` / `mcp.json` — marketplace registration (name `everruns`, version, MCP server URL). * `.claude-plugin/plugin.json` — Claude Code manifest. * `.codex-plugin/plugin.json` — Codex manifest (`defaultPrompt`, `description`). * `.cursor-plugin/plugin.json` — Cursor manifest. * `skills/everruns/SKILL.md` — the agent skill (frontmatter `name: everruns`). * `commands/` — slash commands. `EVERUNS_MCP_URL` selects the deployment the plugin talks to; it defaults to `https://app.everruns.com/mcp`. ## Read the docs as text The documentation site publishes itself as plain Markdown for agents and other tools that would rather read text than HTML. * [`/llms.txt`](https://docs.everruns.com/llms.txt) — the index: the three ways to run Everruns, every documentation set, and the machine-readable surfaces. Start here. * [`/llms-full.txt`](https://docs.everruns.com/llms-full.txt) — every prose page in one file (roughly 250k tokens). * [`/llms-small.txt`](https://docs.everruns.com/llms-small.txt) — the same corpus without the vendor- and operator-specific long tails. * `/_llms-txt/.txt` — one topic at a time, mirroring the sidebar: [framework](https://docs.everruns.com/_llms-txt/framework.txt), [getting-started](https://docs.everruns.com/_llms-txt/getting-started.txt), [built-ins](https://docs.everruns.com/_llms-txt/built-ins.txt), [guides](https://docs.everruns.com/_llms-txt/guides.txt), [integrations](https://docs.everruns.com/_llms-txt/integrations.txt), [explanation](https://docs.everruns.com/_llms-txt/explanation.txt), [reference](https://docs.everruns.com/_llms-txt/reference.txt), [operations](https://docs.everruns.com/_llms-txt/operations.txt). Prefer a set over the complete text. * [`/api/openapi.json`](https://docs.everruns.com/api/openapi.json) — the REST API as OpenAPI 3.0. The text sets carry prose only, so take endpoint shapes from here. Every page in those files begins with its title, its description, and a `Source:` line holding the canonical URL. Cite that URL, not the text file.