
Foreman
A fast classifier watching a slow coding agent, and a policy in ordinary Rust deciding what to do about the numbers. A Framework port of thruwire/foreman, which placed TypeSafe’s Jev above a Codex worker and asked whether semantic supervision can run while the work happens.
What you learn
Section titled “What you learn”How to run a worker session and observe it at the same time: a
Classifier turning bounded evidence into nine
probabilities in one request, and a deterministic policy that owns every
threshold, every limit, and the closed vocabulary of things the supervisor may
do.
The two loops
Section titled “The two loops”The worker keeps its own loop — an Everruns session, or an external CLI in a
child process. session.send returns a receipt immediately, and a child
process is simply left running; either way the supervisory loop reads the
evidence beside the live work. Activity is debounced to a floor, and only a
worker finishing bypasses it. Nothing stops for the factory to think, and a
test holds that claim: it counts readings taken while a worker’s turn is
unresolved and fails if supervision waits its turn.
What it assesses
Section titled “What it assesses”Five questions describe the job (implementation_complete, tests_sufficient,
requirements_satisfied, needs_verification, ready_to_finish) and four
describe the floor right now (meaningful_progress, worker_stuck,
work_off_track, needs_human). Each is a Noul — the probability that a
yes/no statement is true — and all nine ride one request, because questions in
a classification are answered independently and in parallel.
What it may do about them
Section titled “What it may do about them”The classifier only estimates. The policy decides, safety and hard limits
before productivity: escalate when a person is needed or the iteration ceiling
is reached, stop a worker that is off track or stuck, retry once after a stop,
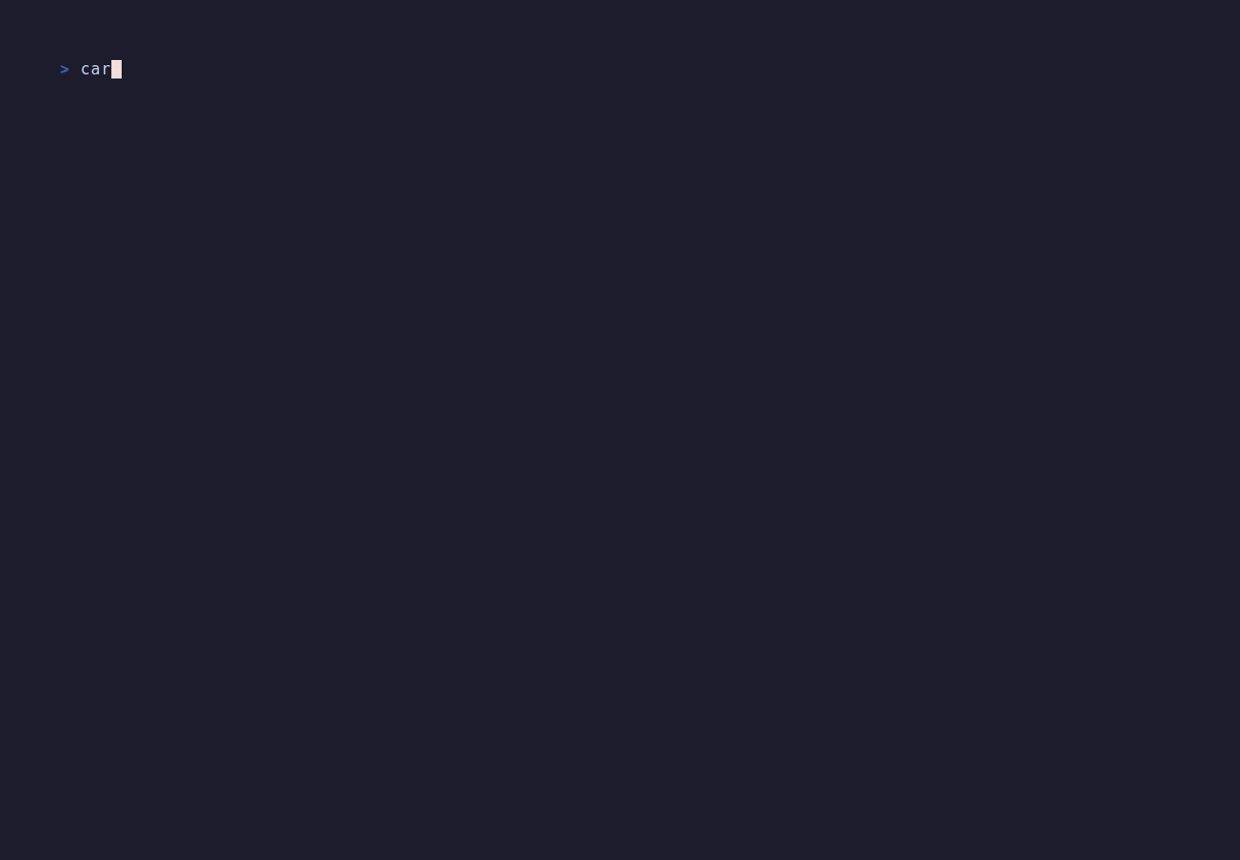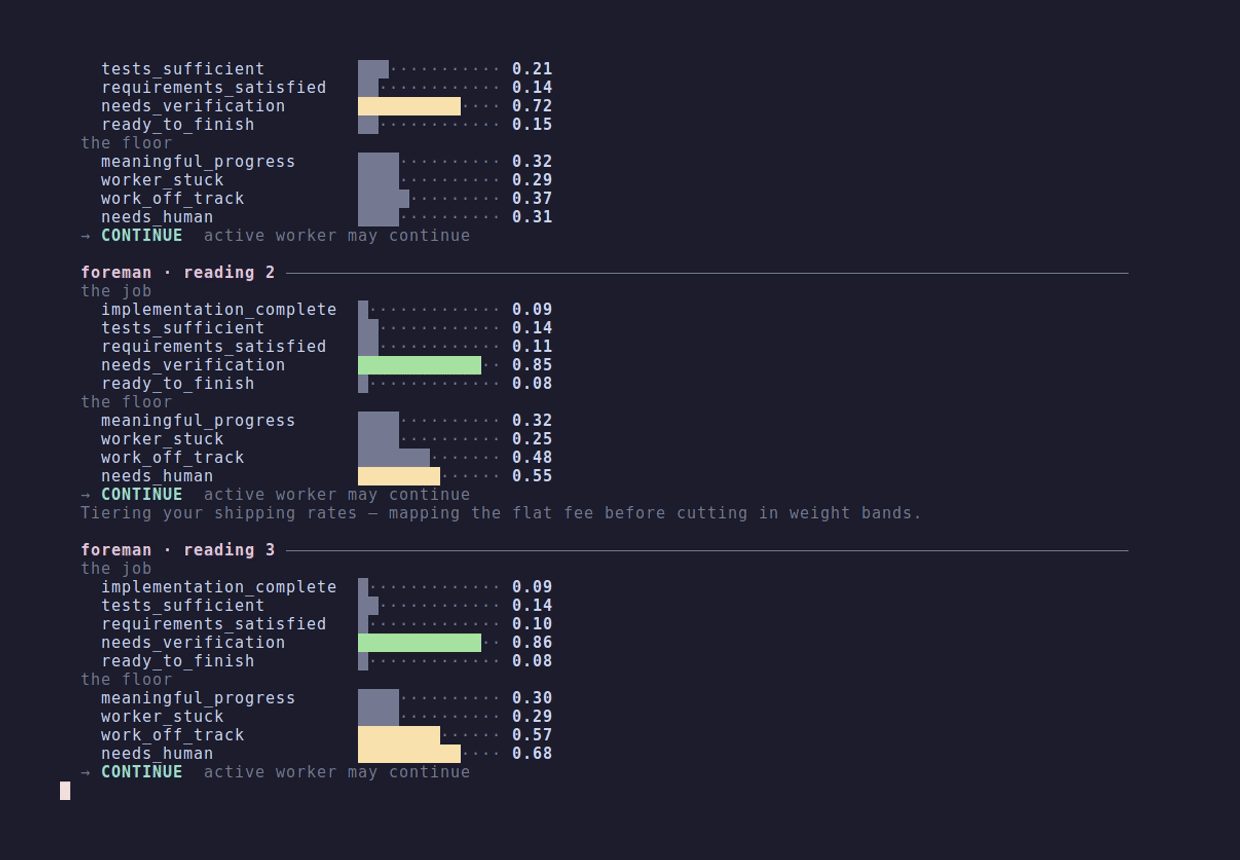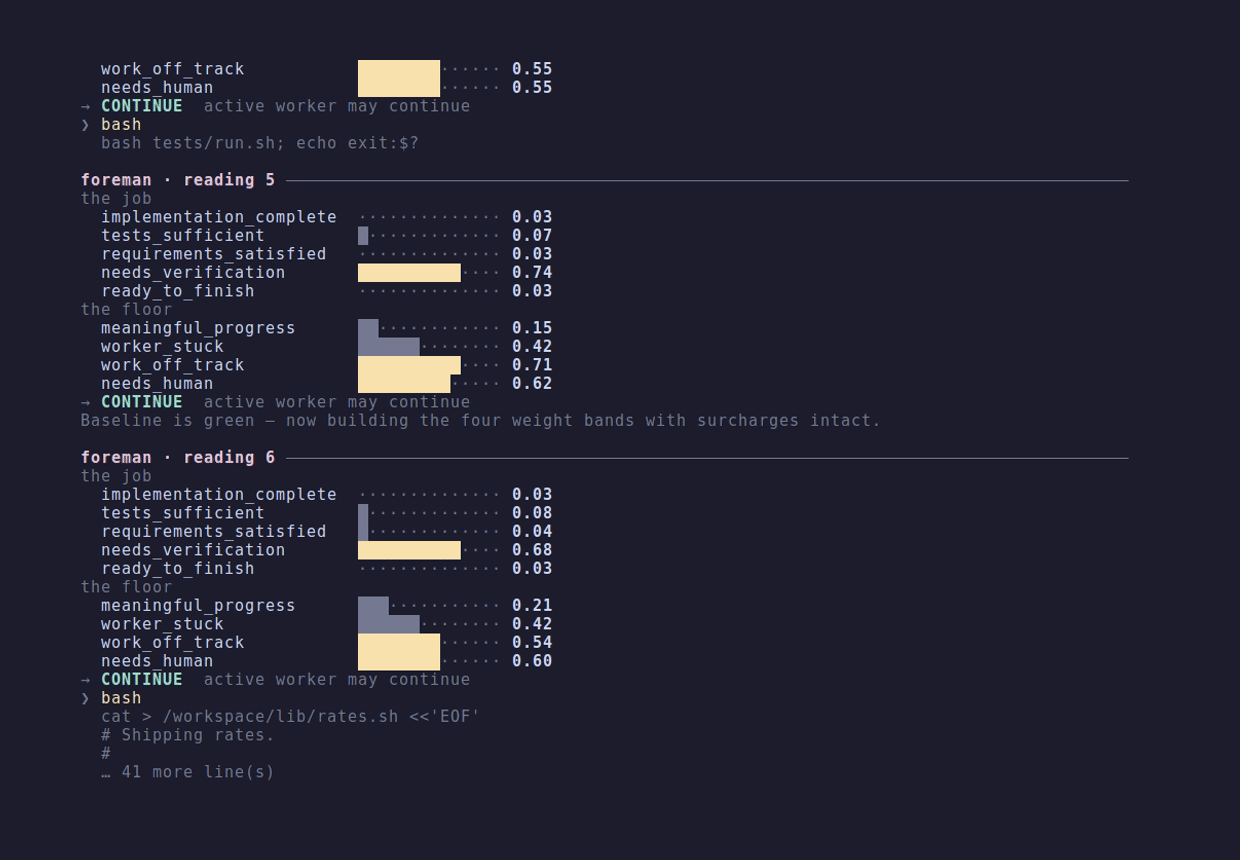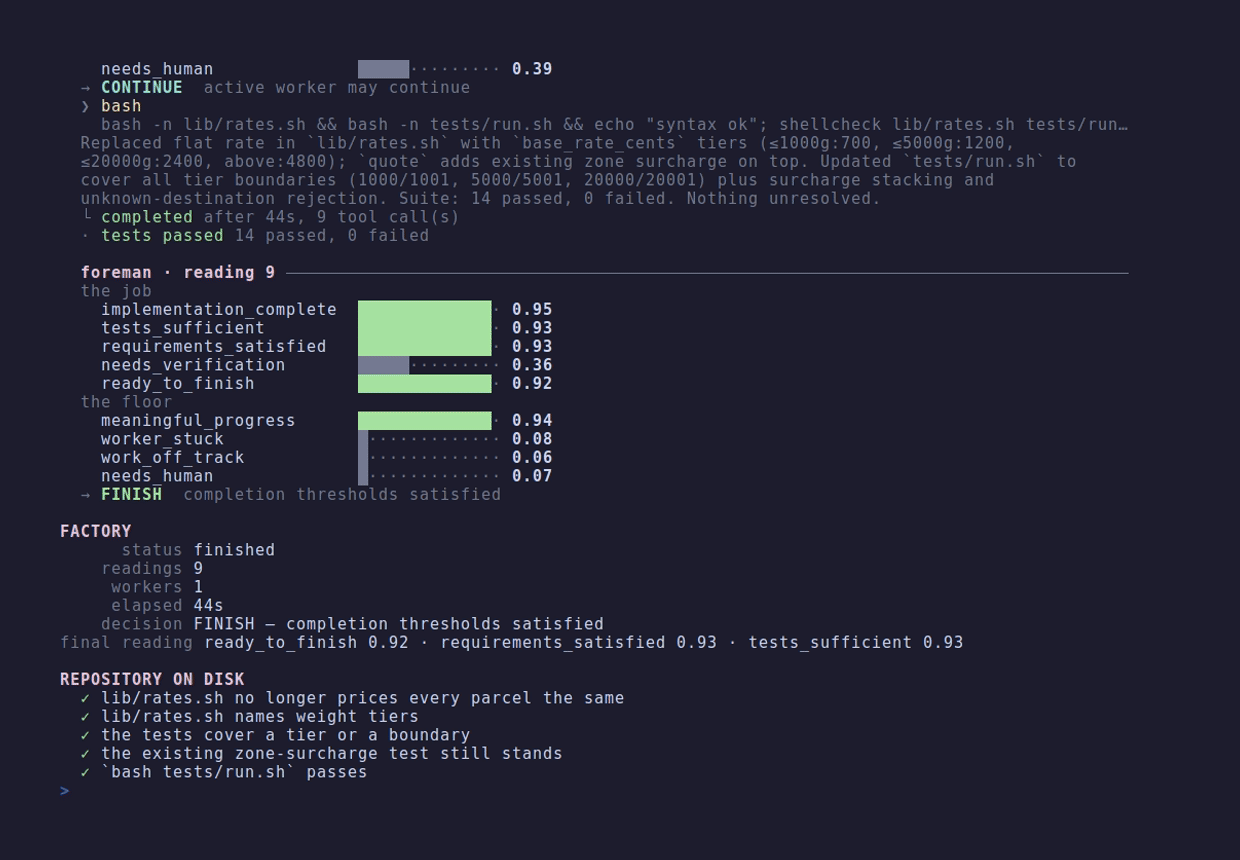
finish when the completion thresholds hold and verification is resolved, start
one independent verifier when a check is warranted, otherwise start or continue
work. Thresholds and limits are Foreman’s defaults and are overridable through
FOREMAN_* environment variables.
What it looks at
Section titled “What it looks at”Never the repository. One bounded snapshot per reading: worker status, elapsed
time, tool calls and output tails, git status, a bounded git diff, the
untracked paths a diff cannot show, recent session events, verification
results, and the previous assessment and decision. An unbounded observation
would make supervision as slow as the work it is watching.
That snapshot goes to the classifier’s service on every reading, so a bounded
slice of the repository leaves the machine on every run — point --repo at a
private repository only if that is acceptable for it. demo works on a fixture
it materializes itself, so it carries nothing of yours. The repository content in
an observation is also untrusted input to the classifier, and that it can only
produce a number is the point: the classifier never names an action, and every
action the policy can take is in one readable file.
Run it
Section titled “Run it”Foreman’s own two entry points, and they mean the same things here:
cargo run -p everruns-foreman-agent --bin foreman -- demoforeman run --repo ./my-project --job "Add rate limiting, and test it."Both are real runs — same worker, same classifier, same credentials. The only difference is who chose the repository and the job:
| Command | Repository | Job | Needs |
|---|---|---|---|
foreman demo | a bundled fixture, in a temporary directory | one it ships with | TYPESAFE_API_KEY + the worker’s |
foreman run … | yours, named by --repo | yours, named by --job | the same |
demo exists because a fixed starting state makes the ending checkable: the job
names a rate schedule, so at the end the repository either prices by weight or
it does not. Those checks run at the bottom of the run and read the files, not
the supervisor’s opinion of them.
demo writes its fixture into a temporary directory unless --repo says
otherwise, and run never writes a fixture at all — --repo is your project,
and the only thing that touches it is the worker. It will be modified.
One supervisor
Section titled “One supervisor”There is one, and it is always real: a Classifier, a budget, one request, nine
answers. There is no offline mode and no second supervisor with fabricated
numbers — every run asks a vendor the nine questions. CI cannot, so the test
suite substitutes a different ClassifierService, the Framework’s own seam for
answering typed questions without a vendor, rather than adding a branch to the
supervisor. The stub receives the observation as JSON exactly as a vendor’s
service does and answers from a table keyed by what is on the floor, so the test
exercises the whole request path rather than bypassing it.
The supervisor runs the tests itself
Section titled “The supervisor runs the tests itself”It already runs git rather than asking the worker what changed, and --tests
applies the same reasoning to the suite: a worker reporting its own green tests
is a claim, and a host-run result is a fact. It lands in the observation as
test_results — the field Foreman declares and never fills — and
tests_sufficient moves on it. The suite runs once as a baseline before any
worker starts, then whenever the floor is quiet; between times the last result
is carried with its age, because a stale pass should not read as a fresh one.
Who does the work
Section titled “Who does the work”--worker picks the crew. All three are watched identically, because what the
supervisor reads is a bounded observation and the strongest evidence in one —
the repository’s own diff — is gathered by the host either way.
--worker | What runs | Independent verification |
|---|---|---|
session (default) | An Everruns session on the Bashkit Shell, meta/muse-spark-1.3-contributor through OpenRouter | A second session under the default read-only workspace policy |
codex | codex exec --cd … --sandbox workspace-write --color never --json …, the line Foreman itself runs | The same CLI with --sandbox read-only |
yolop | yolop -C … -p …, its one-shot print interface | Mission only — yolop publishes no read-only mode |
Anything else is a template: --worker-command "mycli --cd {repo} --task {mission}", where both placeholders are substituted as whole arguments so no
shell sees either.
A session is observed through its own canonical event stream, which arrives
already typed. A CLI offers none of that, so an external worker is observed
through stdout and stderr, and a JSONL line that names its own type counts as
a step.
The floor
Section titled “The floor”The bundled fixture is a small shell project that prices every parcel at one
flat rate; the job is to replace that with weight tiers and cover the
boundaries. Shell, deliberately: bash tests/run.sh needs no framework, no
interpreter and no network, so the same suite runs inside the Bashkit sandbox,
on the host, and inside an external agent. On the session crew the coding worker mounts it read-write and the
verifier mounts the same directory under the default read-only policy, so
“independent check” is a property of the mount rather than a request in a
prompt. The supervisor runs git itself rather than asking the worker what it
did, which is also why an external CLI is supervised just as well as a
session.
What the Framework changes
Section titled “What the Framework changes”The architecture is Foreman’s; the runtime underneath it is not. A worker is a session rather than a subprocess, so stopping one is a cooperative turn cancellation instead of a signal to a process group. Evidence is the canonical event stream rather than parsed JSONL. A retry is a fresh session over the same workspace. Read-only verification is a workspace policy. Steering exists — sending into a live turn applies at the next iteration boundary — and is deliberately left out of the policy’s vocabulary so the comparison with the original stays honest.
Limits
Section titled “Limits”This is an architectural experiment, and porting it does not make it a proven one. Classifier accuracy for this use is unproven and the thresholds are uncalibrated: false positives stop useful workers, false negatives let bad work continue. Observations are bounded and therefore incomplete. One coding worker runs at a time, a verifier reports evidence rather than proof, and the session state is in memory.